
Cloudflare Clairic is an AI model for fast, cheap data extraction, and it is worth understanding precisely because it refuses to do the thing most AI tools are sold on: it does not write. Give it a messy email, a photographed receipt or a spreadsheet, tell it which typed fields you want, and it returns those values directly — a name, an order number, a date, an amount — with a confidence score, in a single pass. Our verdict up front: for high-volume document and inbox pipelines, Clairic is a genuinely interesting cost and latency play, but it is a preview-stage specialist, not a general-purpose AI. It belongs at the front of a pipeline, feeding a decision step and then a writing step, not replacing either of them.
Clairic launched on Product Hunt on 23 October 2026 as Cloudflare’s AI model for extracting structured information without generating tokens, and it is available in preview on Workers AI as @cf/cloudflare/clairic. This review covers what it actually does, what it costs, where it breaks, and who should try it first — based on Cloudflare’s own launch post and the independent coverage that followed, not on the launch hype.
What Cloudflare Clairic does
Most teams currently extract data by asking a large language model to read a document and write back an answer. That works, but it is slow, it costs output tokens, the model can invent a number that was never in the file, and you still need a validation step to check the format of whatever it wrote. Clairic attacks that whole pattern. Cloudflare calls it a “System One” extraction model, borrowing the fast-versus-deliberate distinction: it answers in one pass, without reasoning or generating tokens, and it typically responds in under a second.
A request has two parts: the state (your unstructured input, text plus up to four images) and a schema of typed fields you declare in advance. Clairic then returns one typed value per field. The field types matter, because they are the whole product:
- Extracted values: text copied from the input, such as a name, an order ID or a description, returned as a span with character offsets and a confidence score.
- Computed values: numbers, dates, times, datetimes, durations and lists, read from the input or worked out from it, following the rules of their type — two decimals for cents, for example — again with a confidence score.
- Estimated values: values the input does not state but gives evidence for, returned as a distribution inside bounds you declare, on a grid you specify, with a median and an 80% interval. A repair cost is the canonical example.
- Forecasts: up to 64 future steps of a series, again with intervals rather than a single confident number.
Every scalar answer also carries a null probability: the chance that the input simply does not determine the value. When that probability is high, Clairic returns null instead of guessing. In production pipelines, a confident hallucination is far more expensive than an honest blank, because the blank triggers a human check while the hallucination sails into your database or refund decision.
Pricing: what Clairic actually costs
Pricing is where Clairic’s design becomes a business argument. Because it generates no output tokens, there is no output charge at all: you pay for input only, at $0.10 per million input tokens on Workers AI. It undercuts Cloudflare’s own decision model Clef at $0.24 per million input tokens, but it sits above TypeSafe’s Jev decision model at $0.042. Against a general-purpose model used for extraction, the gap is far larger: the comparison model in Cloudflare’s pipeline test, GLM-5.3, is listed at $1.40 per million input tokens plus $4.40 per million output tokens.
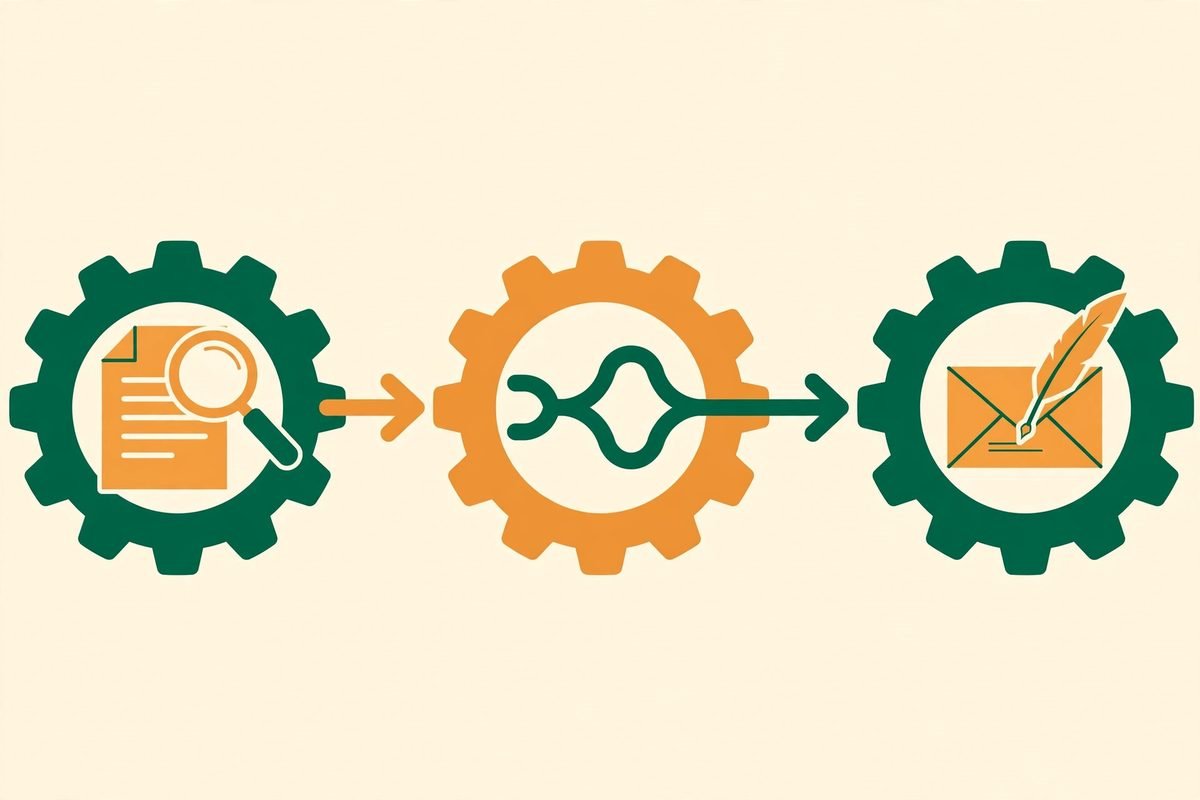
Cloudflare’s headline pipeline test makes the point concretely. In a damaged-product insurance claim workflow, Clairic extracted the facts, Clef applied the company’s rules to choose between refund and repair, and GLM-5.3 wrote the customer reply. That cascade finished in 19.3 seconds against 61.7 seconds for GLM-5.3 doing all three steps, and cost $6,032 per million claims against $11,740 — 49% less. Treat those figures as Cloudflare’s, not independently verified: no independent reproduction has been published yet. Even discounted for vendor optimism, the direction is clear: when extraction is the bottleneck, paying a reasoning model to read every document is the expensive way to do it.
Two pricing caveats belong in any honest review. First, Clairic is in preview, and preview pricing is not a promise about general-availability pricing. Second, the $0.10 figure is input-only, so budget per document, not per token, and measure it on your own files before committing a pipeline to it.
Who Clairic is for
Clairic is for teams with a specific shape of problem: high volumes of semi-structured input, a stable set of fields, and a downstream system that can act on typed values. The strongest fits we see are support and operations teams triaging customer emails into tickets, finance teams pulling totals, dates and vendor names from invoices and receipts, logistics teams reading delivery notes and damage reports, and any team feeding a CRM, a claims system or an internal dashboard from documents that arrive as prose rather than forms.
It is also a natural fit for agent builders. An agent that spends its reasoning budget reading every attachment is burning money and latency on the least valuable step. Putting Clairic first — extract with Clairic, decide with a decision model like Clef, write with an LLM only where prose is actually needed — is exactly the cascade Cloudflare demonstrates. Our AI integration and automation services increasingly start from this split: use the cheapest model that can do each step well, and reserve the expensive model for the step only it can do.
Watch-outs and honest limitations
Cloudflare is unusually candid about Clairic’s limits, and you should take them seriously. First, multi-step arithmetic is not yet reliable. One- and two-step calculations — totals, differences, date math — are reported as solid, but longer chains of dependent calculations are not. Cloudflare’s own advice is to let Clairic extract the inputs and do the maths in your code. If your pipeline needs a model to aggregate across many table rows or chain dependent calculations, Clairic is the wrong tool for that step today.
Second, forecasting is basic. Cloudflare’s showcase ran Clairic on 21 days of TSA passenger counts: forecasts were off by 3.3% on average, and 17 of the 21 actual counts landed inside the model’s 80% interval. It cannot read holiday effects that do not appear in the series, and forecasts several steps out flatten toward the average. Do not replace a dedicated time-series model with Clairic on the strength of one demo.
Third, there are practical preview constraints. The context window is 65,536 tokens, with up to four images per request, and images must be embedded as PNG, JPEG or WebP — passing an image URL is not supported. Open weights are promised “soon” with no date and no licence named. If self-hosting is a requirement rather than a nice-to-have, wait for the weights rather than building on a promise.
Finally, Clairic does nothing after extraction. It does not look up the order, approve the refund or reply to the customer. Any vendor pitch that implies otherwise is overselling. Budget for the decision and action layers, and keep human review in place for any step where an error costs real money — payments, refunds and compliance filings most of all.
How Clairic compares to the alternatives
Clairic sits in a small but fast-moving category. Clef, its sibling, is a decision model: you list the options and it returns a probability for each, rather than extracting a value that cannot be listed in advance. Jev, from TypeSafe AI, is also a decision model, and is cheaper per input token, but it answers a different question — which option, not what value. General-purpose LLMs like GLM-5.3 can do extraction, decision and writing in one model, but they do it slowly, expensively and with the hallucination risk that Clairic’s null behaviour is designed to avoid. The honest comparison is therefore not “which model is best” but “which step deserves which model”. Clairic wins the extraction step on speed and cost; it does not compete for the writing step at all.
Against traditional extraction tooling — regular expressions, template parsers and OCR pipelines — Clairic’s advantage is tolerance for mess: templates break when a supplier changes an invoice layout, while a model with confidence scores degrades more gracefully and its nulls flag exactly which documents need a human. For stable, single-format documents, a good template parser may still be cheaper; for varied, human-written input, Clairic is the stronger bet.
From our experience: how to evaluate Clairic properly
Having shipped document and workflow automation for clients over 9+ years and 300+ projects, our advice is to evaluate Clairic on your ugliest real documents, not on a clean demo set. Take 200 genuine emails, invoices or claim notes — including the scanned, the misspelled and the incomplete — define your field schema, and measure three things: field accuracy against a human-labelled ground truth, the null rate (high nulls mean your schema or your input needs work, not that the model failed), and cost per document at your real input sizes. Then run the same set through your current LLM approach and compare total pipeline cost, not model price alone, because the cascade — Clairic plus decision plus writing — is the unit that matters.
Two gotchas are worth planning for. First, confidence thresholds are a product decision: decide in advance what auto-accepts, what routes to a human, and what rejects, and log every decision so you can tune from real outcomes. Second, schema design is the work: a vague field will return vague results, while a typed field with units and decimal rules will not. If you want help designing that kind of pipeline, browse our AI Tools Directory for comparable tools, or talk to us about the workflow itself before you buy anything.
Frequently asked questions
What is Cloudflare Clairic?
Clairic is Cloudflare’s extraction model on Workers AI. You give it unstructured text and up to four images plus a schema of typed fields, and it returns one typed value per field — extracted, computed, estimated or forecast — with a confidence score, without generating any prose.
How much does Clairic cost?
Clairic costs $0.10 per million input tokens on Workers AI, with no output-token charge, because it generates no output tokens. Your real cost per document depends on how much input you feed it, so measure it on your own files during the preview.
Is Clairic a replacement for ChatGPT or Claude?
No. Clairic cannot write, reason through open-ended problems or hold a conversation. It is a specialist for the extraction step of a pipeline. In Cloudflare’s own example, Clairic extracts, Clef decides and a general LLM writes the reply. Use each model for the step it does best.
Can Clairic handle complex calculations?
Only simple ones. One- and two-step calculations such as totals and date differences are reported as reliable, but longer chains of dependent calculations are not yet. Cloudflare advises extracting the inputs with Clairic and finishing the maths in your own code.
Should my business adopt Clairic now?
If you process high volumes of varied documents and your current LLM extraction bill or latency hurts, run the 200-document evaluation described above during the preview. If you need self-hosted weights, guaranteed pricing or complex calculation support, wait: those are promised or partial today, not delivered.
Clairic is a small, sharp idea executed at the right moment: stop paying a storyteller to read your invoices. For teams whose bottleneck is genuinely extraction — high volume, messy input, typed output — an AI model for fast, cheap data extraction is worth a serious trial, with its limits priced in from day one. Evaluate it on your worst documents, and keep humans on the expensive decisions.