
API rate limiting best practices are the difference between an API that survives its own success and one that falls over the week a big customer onboards. This guide is written for developers and technical founders who build or maintain APIs. By the end, you will know which limiting algorithm fits your workload, which headers to return so clients can pace themselves, and the configuration mistakes that cause real outages in production.
Rate limiting is not a feature you bolt on after launch. It is load-bearing infrastructure. Every public API you admire — Stripe, GitHub, Twilio — treats limits as part of the product: documented, predictable, and enforced at the edge. The good news is that the patterns are well understood. The bad news is that the wrong pattern, or the right pattern misconfigured, is a favourite way to take a healthy service down.
Why rate limiting is not optional
Three things force the issue. First, cost: every request burns compute, database connections, and third-party API calls. One enthusiastic customer with a runaway script can double your infrastructure bill before anyone notices. Second, fairness: without limits, one tenant’s traffic spike becomes every tenant’s latency spike. Third, security: credential stuffing, scraping, and brute-force attacks are all just unauthorised traffic at volume, and a limiter is the cheapest layer of defence you own.
There is a fourth reason people discover too late: your downstream dependencies have limits too. If your API fans out to a payment provider, a CRM, or an LLM endpoint, their quotas become your quotas. Rate limiting at your edge is how you translate someone else’s ceiling into orderly behaviour on your side, instead of a cascade of timeouts.
The four rate-limiting algorithms, and when each earns its place
Every limiter you will ever meet is one of four ideas, or a combination. Understanding them takes ten minutes and pays off every time you configure a gateway.
Fixed window
The simplest design: allow N requests per fixed interval — say, 100 requests per minute — then reset the counter at the boundary. It is trivial to implement with a single counter in Redis. Its flaw is the boundary stampede: a client can legally make 100 requests at 11:59:59 and 100 more at 12:00:01, hitting your backend with 200 requests in two seconds. Use fixed window only for low-stakes endpoints where a 2x burst is harmless.
Sliding window log
Store a timestamp for every request and count how many fall inside the last N seconds. This kills the boundary problem completely — the window rolls continuously. The price is memory: one timestamp per request per client, which gets expensive at scale. In practice, teams use the cheaper sliding window counter approximation (weighted blend of the current and previous fixed window) and reserve exact logs for low-volume, high-value endpoints.
Token bucket
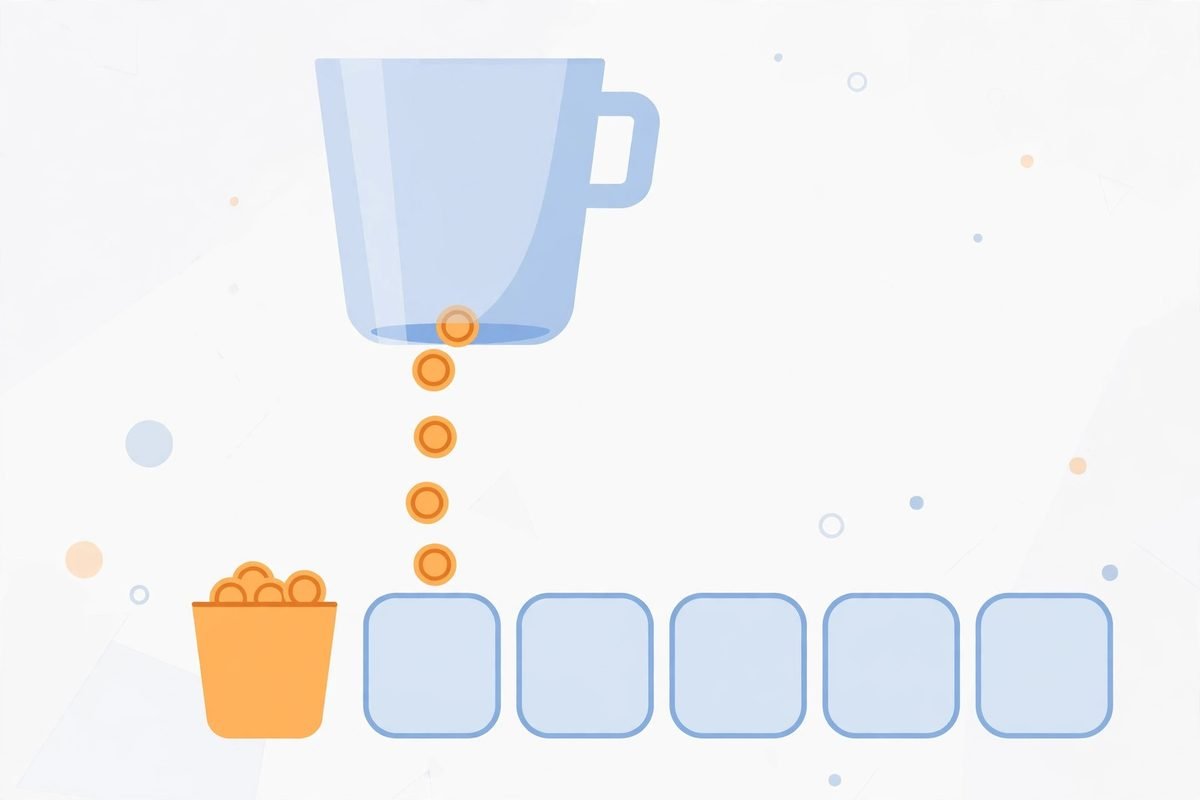
Each client has a bucket holding up to B tokens, refilled at R tokens per second. Every request costs one token; an empty bucket means rejection. Token bucket is the workhorse of production APIs — a widely cited 2026 implementation guide notes it is the pattern behind GitHub and Stripe’s limits — because it handles bursts gracefully: a full bucket absorbs a short burst, while the refill rate caps sustained traffic. If you only learn one algorithm, learn this one.
Leaky bucket
Requests enter a queue and drain at a constant rate; a full queue drops new arrivals. Leaky bucket smooths traffic into a perfectly steady flow, which is exactly what you want when protecting a fragile downstream — a legacy database, a payment processor, an LLM endpoint with strict quotas. The trade-off is latency: requests wait in the queue, and bursts are penalised rather than absorbed.
The short version: token bucket for bursty client traffic, leaky bucket for steady downstream protection, sliding window when precision matters more than memory, fixed window only where a burst cannot hurt you.
API rate limiting best practices for headers and 429 responses
Returning HTTP 429 (Too Many Requests, standardised in RFC 6585) is only half the job. A limiter that just says “no” trains clients to retry blindly — which is how a small spike becomes a self-inflicted denial of service. Good limiters teach clients how to behave by communicating state on every response, not just the rejected ones.
Send these headers on successful responses too, so well-built clients can pace themselves before they ever see a 429:
X-RateLimit-Limit— the maximum requests allowed in the current window.X-RateLimit-Remaining— how many requests the client has left.X-RateLimit-Reset— when the window resets, as a Unix timestamp.Retry-After— seconds to wait before retrying. Required on every 429.
If you are building a new API today, consider the IETF standard headers RateLimit and RateLimit-Policy (RFC 9334) alongside the classic X-RateLimit-* trio. They describe quota state and policy in one structured format, which is why newer platforms are adopting them — email API provider Resend, for example, built its rate-limit headers in conformance with the IETF standard specifically to ease client adoption. Keep the classic headers too; most client libraries already parse them.
Make the 429 body as structured as your success responses: a stable error code, a human-readable message, and recovery hints in the same envelope your API always uses:
{"error": {"code": "rate_limit_exceeded", "message": "Too many requests. Please retry after 12 seconds.", "retry_after_seconds": 12, "limit": 60, "remaining": 0}}
Predictability is the whole game. Same status code, same fields, same meaning on every endpoint — so a client’s retry logic written once works everywhere.
Layer your limits: per key, per IP, per endpoint
One global limit is a single point of policy failure. Production APIs layer limits so that one abusive client, or one expensive endpoint, cannot take down everyone else:
- Per API key / per user — the fairness layer. Each tenant gets their own quota, so one customer’s runaway script degrades only that customer.
- Per IP — the abuse layer. Catches unauthenticated scraping and credential stuffing before it reaches your application logic. Set it looser than per-key limits.
- Per endpoint — the cost layer. A
GET /statushealth check and aPOST /reportsthat fans out to five services must not share a budget. Price limits in the currency of cost: expensive operations get tighter quotas. - Global — the survival layer. A coarse ceiling that protects the infrastructure itself when everything else fails.
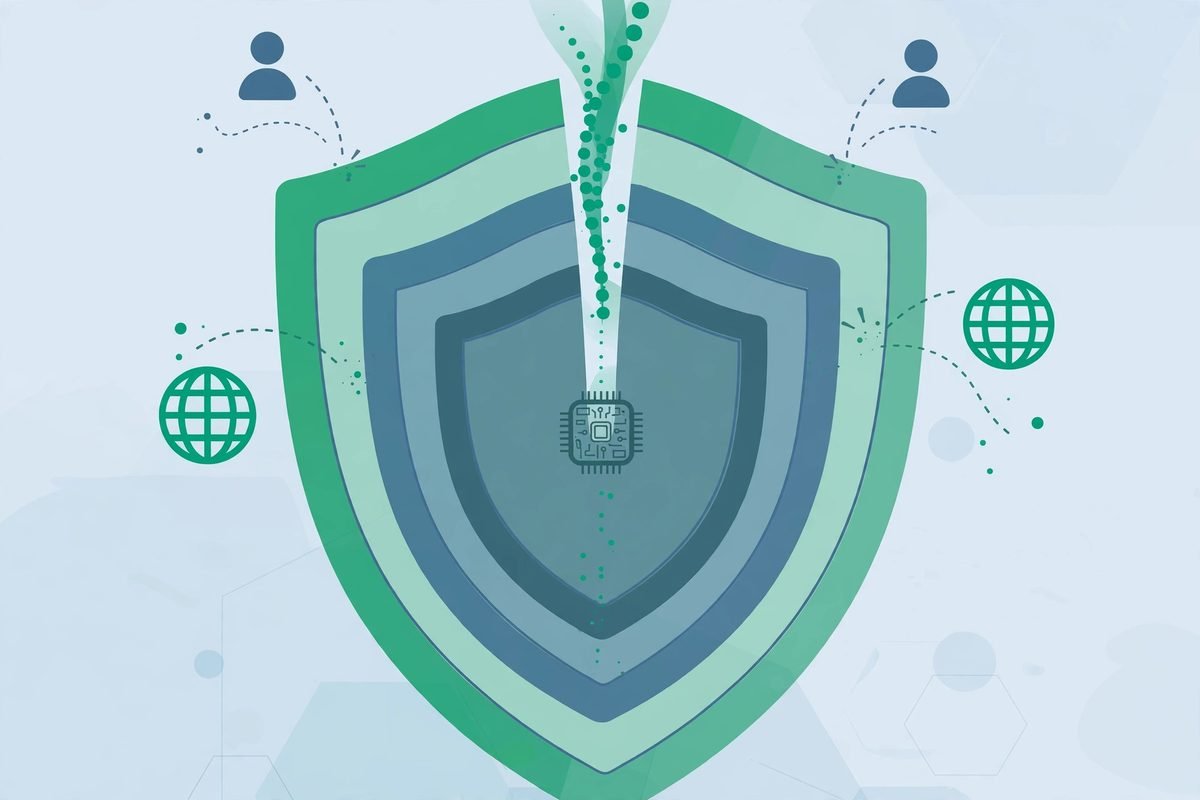
Enforce at the edge — in your API gateway, load balancer, or a sidecar like NGINX, Kong, or Envoy — not deep inside application code. The limiter should reject bad traffic before it consumes a database connection. Use a shared, fast store (Redis is the standard) so limits are consistent across every instance behind the balancer; a per-process in-memory counter lets a client multiply their quota by your instance count.
From our experience: the mistakes that actually cause outages
Across nine years of building and integrating APIs, we have seen the same misconfigurations cause the same outages. Here are the ones worth memorising:
1. Keying limits to IP addresses behind shared NAT
An office, a university, or a mobile carrier can put hundreds of legitimate users behind one IP. A strict per-IP limit turns into a support ticket storm. Always prefer authenticated identity (API key, user ID) as the primary key, and keep per-IP limits generous — they exist for abuse, not fairness.
2. Rate limiting before authentication
If the limiter runs before auth, an attacker burning through fake credentials consumes the same quota pool as real users — and worse, your error responses leak whether a username exists before the limit kicks in. Authenticate first, then limit by the authenticated identity. Keep a separate, coarse unauthenticated limit for the login endpoints themselves.
3. One limit for cheap and expensive endpoints
We once audited an API where a 5-millisecond status check and a report endpoint that triggered a 40-second database aggregation shared the same 1,000-requests-per-minute quota. One customer polling the report endpoint at full tilt starved every other integration on the platform. Price your limits by cost: tier endpoints by resource weight and give the heavy ones their own, much smaller budgets.
4. The limiter itself becomes a single point of failure
A Redis-backed limiter is only as reliable as Redis. Decide the failure mode in advance: fail open (allow traffic when the limiter store is down — availability over protection) or fail closed (reject — protection over availability). Most business APIs should fail open with alerting, because a dead Redis should not take down the product. Whatever you choose, make it a conscious decision, not a 3 a.m. discovery.
5. No Retry-After, so clients retry harder
A bare 429 with no Retry-After is an invitation to a retry storm: the client guesses, guesses wrong, retries immediately, and multiplies the load that triggered the limit. Always return a concrete wait time, and document an exponential backoff strategy (1s, 2s, 4s, capped around 30–60 seconds) in your API docs so clients converge on polite behaviour.
Honourable mention: forgetting webhooks and callback endpoints. Your inbound limiter protects your API, but the endpoints that receive webhooks from payment providers and CRMs need their own treatment — queue them, verify signatures, and never let a provider’s retry burst consume your main quota. When we plan custom API development for clients, webhook handling gets its own rate-limit design from day one.
Teach your clients to behave
The best limiter is one clients rarely hit, because you taught them the rules up front:
- Document limits per endpoint, not just globally. “60 requests per minute” is useless if the expensive endpoint allows 5.
- Warn before you punish. When a client crosses roughly 80% of quota, include a warning field or header so they can slow down before requests start failing.
- Publish a backoff recipe. Exponential backoff with jitter, a stated maximum wait, and explicit guidance on when to stop retrying and surface the error to a human.
- Ship SDK helpers. If you maintain client libraries, build header parsing and automatic backoff in — most integrators will never read your docs, but they will use your SDK.
Getting the economics right matters as much as the engineering: if you are scoping the work, our breakdown of what a real API integration project costs in 2026 covers the pricing side of this same conversation.
Frequently asked questions
What is the best rate limiting algorithm for a REST API?
Token bucket is the safest default: it absorbs short bursts while capping sustained traffic, and it is the pattern behind the limits at GitHub and Stripe. Use leaky bucket when you need to protect a fragile downstream with a perfectly steady flow, and sliding window when precision matters more than memory cost.
What headers should a rate-limited API return?
Return X-RateLimit-Limit, X-RateLimit-Remaining, and X-RateLimit-Reset on every response — not just 429s — plus Retry-After on every 429. For new APIs, also consider the IETF standard RateLimit and RateLimit-Policy headers (RFC 9334) for structured quota communication.
How should clients handle HTTP 429 responses?
Read the Retry-After header and wait exactly that long before retrying. If no header is present, use exponential backoff with jitter — 1 second, then 2, then 4, capped around 30–60 seconds — and stop retrying after a handful of attempts so a persistent problem surfaces to a human instead of hammering the API forever.
Should rate limiting run before or after authentication?
Authenticate first, then limit by the authenticated identity (API key or user ID). Rate limiting before auth lets attackers consume shared quota and can leak account-existence signals. Keep a separate coarse limit on the login and token endpoints themselves to blunt brute force.
How do you rate limit a GraphQL API?
Request counting breaks down with GraphQL because one query can cost 1 unit or 10,000. The standard approach is cost-based limiting: assign each field a complexity score, sum the query’s total cost before executing it, and deduct from the client’s budget. Reject queries over a maximum complexity outright — it is the GraphQL equivalent of a per-endpoint tier.
Rate limiting done right is invisible: clients pace themselves from your headers, expensive endpoints carry their own budgets, and the limiter degrades gracefully instead of becoming the outage. If your API is growing past the point where “we’ll add limits later” still sounds responsible, talk to our team — designing quota systems that survive real traffic is part of the custom API work we do every week.