
Billion Context is a context compression plugin for AI coding agents that promises something most agent-heavy teams would pay real money for: a single coding session that runs for days or even weeks — billions of tokens through one conversation — inside a modest 100K-token context window, using a claimed five times fewer tokens. The project, by GitHub user ranxianglei, has climbed to around 1,700 stars with fresh commits landing daily, and its README reads less like a weekend hack and more like infrastructure: a local proxy that sits between your coding agent and the model API, rewriting Anthropic and OpenAI streams with its own acp-kernel compression. This post walks through what it is, how it works, what the real evidence looks like, and where we would be cautious before rolling it out to a team.
What context compression for AI coding agents actually looks like
The core idea is simple; the execution is where it gets interesting. Every call your coding agent makes re-sends the entire conversation history — every tool result, every file read, every earlier plan — and providers charge per token, so long sessions get expensive long before they get long. The usual fix is the agent’s built-in compactor: hit the window limit, squash everything into one summary, lose the detail, start drifting. Billion Context takes a different route: it never lets the context get unwieldy in the first place. A local proxy watches the conversation grow, and the model itself decides — through injected tools — when to fold older message ranges into layered summaries and when to pull them back.
What makes this more than a summariser script is the design around it. Compression is incremental (small ranges at a time, not one big squash), reversible (any range can be decompressed back to full detail on demand), and prefix-cache friendly (the cache prefix stays intact, so your provider’s cached-token discounts keep working). In a healthy session the project reports a 95–97% prefix-cache hit rate, with compression itself costing at most about 2% of tokens. Those are the author’s own numbers — we will come back to how seriously to take them.
What Billion Context can do
- Sit between a supported coding agent and its model API, rewriting Anthropic/OpenAI-shaped streams on the fly — no model retraining, no special API.
- Let the model manage its own memory: four context-management tools are injected into the conversation, and the model calls them itself as context grows.
- Compress consumed conversation into layered summaries, so a single session can keep going for days — the project talks about month-long sessions and billions of tokens through one context window.
- Preserve cache behaviour: summaries are written in small ranges, the cache prefix stays intact, and ranges stay folded in history until explicitly restored.
- Plug into roughly two dozen clients — Claude Code, Codex, OpenCode, pi, Kimi, Z.ai’s zcode, Qwen Code, Gemini CLI, GitHub Copilot CLI, Aider, Goose, Zed, Crush, Amp and more — via native plugins, a one-command launcher, or a base-URL rewrite.
- Keep the model in charge of the decision: there is no hard truncation limit; the model decides when and what to compress into high-fidelity summaries.
- Ship with unusually serious documentation, including an open paper on “Model-Driven Incremental Hierarchical Compression” and client-by-client integration guides.
How it works under the hood
The architecture is a proxy pipeline with five steps. You point your agent’s base URL at the proxy (or install it as a native plugin, or launch both together), and then:
- Parse the request — the proxy accepts both Anthropic and OpenAI request shapes.
- Run acp-kernel compression over the conversation, deciding which ranges are safe to fold.
- Inject a
compresstool plus a compression philosophy into what the model sees. - Forward the request to the real model API — your keys, your billing, unchanged.
- Rewrite the streaming response on the way back, keeping the agent’s UX intact.
The four injected tools are the part your model actually touches: compress folds a message range into a detailed summary, decompress restores a range when exact details are needed again, search_context runs keyword search over compressed summaries and visible messages, and acp_status gives a context-usage overview plus which ranges are still compressible. The proxy executes compress server-side so folded ranges stay summarized in history until restored.
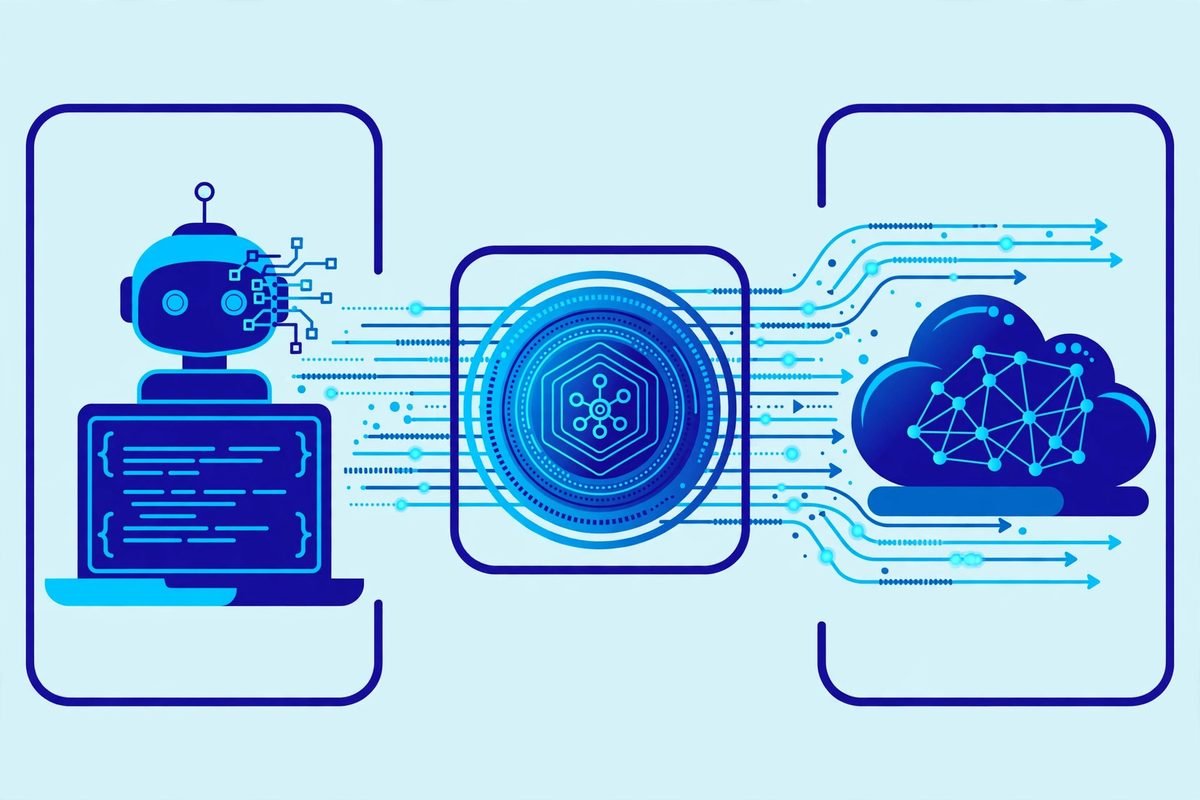
Three integration styles cover nearly every setup. The native plugin (bili plugin install opencode) embeds the proxy inside the client so you start the client exactly as usual. The launcher (bili claude) brings up the proxy and the client together without touching any config file. The URL prefix style just points your client’s base URL at the proxy with a /bili/ prefix — the universal fallback. One gotcha straight from the README: native plugins and the older standalone extensions are mutually exclusive — run both and you get double compression. The installer handles the switch and snapshots your original config, but it is worth knowing.
Why it is trending right now
Context exhaustion is the number-one complaint about coding agents, and token bills are the number-two complaint — Billion Context aims at both at once. The pitch that resonates with teams is the combination of small context windows (100K is enough) and 5x fewer tokens: pair a cheaper or smaller-window model with aggressive compression and your agent API bill drops while sessions get longer. That is the token-economics story, and it lands at exactly the moment agent coding has gone mainstream and finance departments have started asking questions. You can see the same economics conversation playing out across the AI tools directory we maintain — cost per useful output is becoming the metric teams actually optimise.
The other reason it stands out: evidence. The project ships a living, open paper and reports a 4.5-month longitudinal study behind the claims — three hosts, 174,327 model calls, 18.76 billion cumulative input tokens (about 24.7 billion across all hosts), zero context-window violations on 204,800-token models, and marathon sessions of 8,584–12,049 calls. That is unusual rigour for a project at 1,700 stars, and it reads like the author wants the mechanism judged, not just the marketing. It is still the author’s own data, not an independent benchmark — but as a signal of seriousness, it is strong.
Getting started: install and first run
- Install with a user-level prefix (no sudo):
npm install -g billion-context --prefix=~/.local. This puts thebilicommand in~/.local/bin, which is already on PATH in most distros. The README is explicit: avoid sudo and reinstall with the same prefix flag on future updates. - Pick your integration style. Native plugin where supported (
bili plugin install pi), launcher for zero config (bili opencode), or the/bili/URL prefix for everything else. A manualbili startdaemon owns port 8787; spawned lanes live from 18787 upward and hop +1 on collisions. - Watch cache health. A healthy session keeps a 95–97% prefix-cache hit rate. Sustained lower? The FAQ lists the usual suspects in order: upstream cache TTL expiry, a model switch mid-session, a genuine bug, or something unknown — with
/acpand/acp-cachecommands to attribute it. - Try it on a genuinely long task first. Short sessions will not show you much; the value appears when the model starts folding ranges itself. Use
decompressany time you need exact detail back.
From our experience: what we would watch before adopting it
We run agent coding at real scale on client work, so here is the honest read. First, the architecture means a stream-rewriting proxy sits between your agent and the API and sees every byte in both directions — your code, your prompts, your API traffic. Self-hosted on a trusted machine that is fine, and the code is public TypeScript you can review; we would not casually route sensitive client repositories through it on shared or CI machines without reading the source first. A couple of integration paths also use local certificate interception for closed binaries, which is fiddly by nature — prefer the native plugin where your client supports one.
Second, treat it as the young project it is. Around 1,700 stars with one dominant author is a fine place to start, not a place to bet a production pipeline on day one: pin your versions, try it on non-critical work, and watch how it behaves with your specific model and provider before standardising. The headline “5x fewer tokens” is the author’s claim from their own study; your mileage will vary with task shape, model, and provider cache TTLs. What we find genuinely compelling is not the multiplier but the mechanism — incremental, reversible, model-driven compression with cache discipline is a better answer than every hard-truncation compactor we have used, whatever the exact savings turn out to be. For teams already investing in AI integration and automation, this is the kind of tooling that compounds: the longer your agents run, the more context discipline matters.
When would we not use it? Short sessions where setup cost exceeds savings, environments where you cannot install a local CA, and regulated settings where a stream-rewriting proxy is a compliance headache. And for anything where the exact transcript is the record — security audits, legal review — keep the uncompressed log too. Compression is a working convenience, not an archive.
Frequently asked questions
Is Billion Context free to use?
The repository is public on GitHub and ships through npm, and its accompanying research paper is MIT-licensed — but GitHub’s own license field is currently unset, so check the repo’s LICENSE file before relying on it commercially. Self-hosting means your only cost is the model API tokens you already pay for.
Which coding agents does Billion Context work with?
Roughly two dozen, including Claude Code, Codex, OpenCode, pi, Kimi, Z.ai’s zcode, Qwen Code, Gemini CLI, GitHub Copilot CLI, Aider, Goose, Zed, Crush and Amp. Integration comes in three flavours: a native plugin inside the client, a one-command launcher, or pointing your client’s base URL at the proxy with a /bili/ prefix.
How is this different from my agent’s built-in context compaction?
Built-in compactors usually truncate or summarise everything at a hard limit. Billion Context is incremental and reversible — the model compresses message ranges as it chooses, you can decompress any range back to full detail, and the design stays prefix-cache friendly so provider cached-token discounts keep working.
Will compression lose details I need later?
That is the honest risk with any summarisation, and this project mitigates it better than most: on-demand decompression plus keyword search over compressed ranges, with the author reporting 95–97% prefix-cache hit rates in healthy sessions. For anything where exact detail is non-negotiable, we would still keep the uncompressed transcript alongside.
Can one session really process billions of tokens?
That is the project’s own reported result from a 4.5-month longitudinal study: 174,327 model calls and 18.76 billion cumulative input tokens with zero context-window violations on 204,800-token models. It is the author’s data, not an independent benchmark — treat it as evidence of seriousness rather than a guarantee.
If your team is burning real budget on agent API calls, context compression is one of the highest-leverage places to look — and Billion Context is the most serious open attempt at it we have seen this year. It is young, it is opinionated, and it deserves a trial on non-critical work before anywhere else. If you want help evaluating it — or building the workflow automation around your agent stack — talk to us. We build this stuff every day.