
If your agents search the web all day, search stops being a feature and becomes a bill. Every research loop, every lead-enrichment run, every support bot that checks a changelog before answering is quietly spending money on retrieval — and then spending again on the tokens needed to read what it found. That is the cost problem Exa 3.0 is aimed at, and it is why this release matters more than its benchmark table suggests.
Exa 3.0, released on 18 October 2026, is a new version of Exa’s search engine for AI agents, with a cheaper Lite tier and a token-saving highlights feature now generally available. In short, this is AI search for agents at lower cost, with a trade-off you should understand before you switch: you pay less per request, but you are buying a lighter retrieval pass, not the full-strength one. For high-volume, well-understood queries, that trade is often worth it. For hard, open-ended research, it may not be. This review works through what Exa 3.0 actually does, what it costs, where it fits, and where its claims still need your own testing.
What Exa 3.0 does — AI search for agents at lower cost
Exa is not a search box for people. It is an API that lets software ask the web a question and get structured, machine-readable results back: ranked pages, extracted contents, and, where asked, a direct answer. Agents use it inside coding tools, research workflows, sales-enrichment pipelines and support bots, where a human would previously have opened a browser and skimmed ten tabs.
Version 3.0 changes the retrieval stack underneath that API in three ways, according to Exa’s own announcement. First, it trains a larger embedding model, with more compute and data than any previous Exa model, to match the meaning of a query rather than only its keywords. Second, it adds billions of documents to its index across data types that agents increasingly ask about: products, local businesses, flights, events, sports and weather, alongside the usual web pages. Third, it makes Dynamic Highlights generally available, which is the feature that does most of the cost work, as explained below.
That index expansion matters because agent queries no longer look like human queries. A person searches for a restaurant; an agent searches for every restaurant near a venue that is open on a given date, has a private room, and lists a phone number. An index built only for article-style pages will miss much of that, and Exa is explicitly building for the second kind of query.
What is new in Exa 3.0?
Exa Lite is the new search type, priced at $4 per 1,000 requests. It runs on the same index as Exa Auto, but with less compute spent on candidate generation, highlights and ranking. Exa Auto, at $7 per 1,000 requests, is the higher-quality tier for queries where retrieval quality matters more than unit cost. Together, Exa says, Lite and Auto set a new Pareto frontier for search — meaning that no rival it tested offered the same quality at a lower price, or higher quality at the same price. Treat that as a vendor claim to test, not as an independent finding.
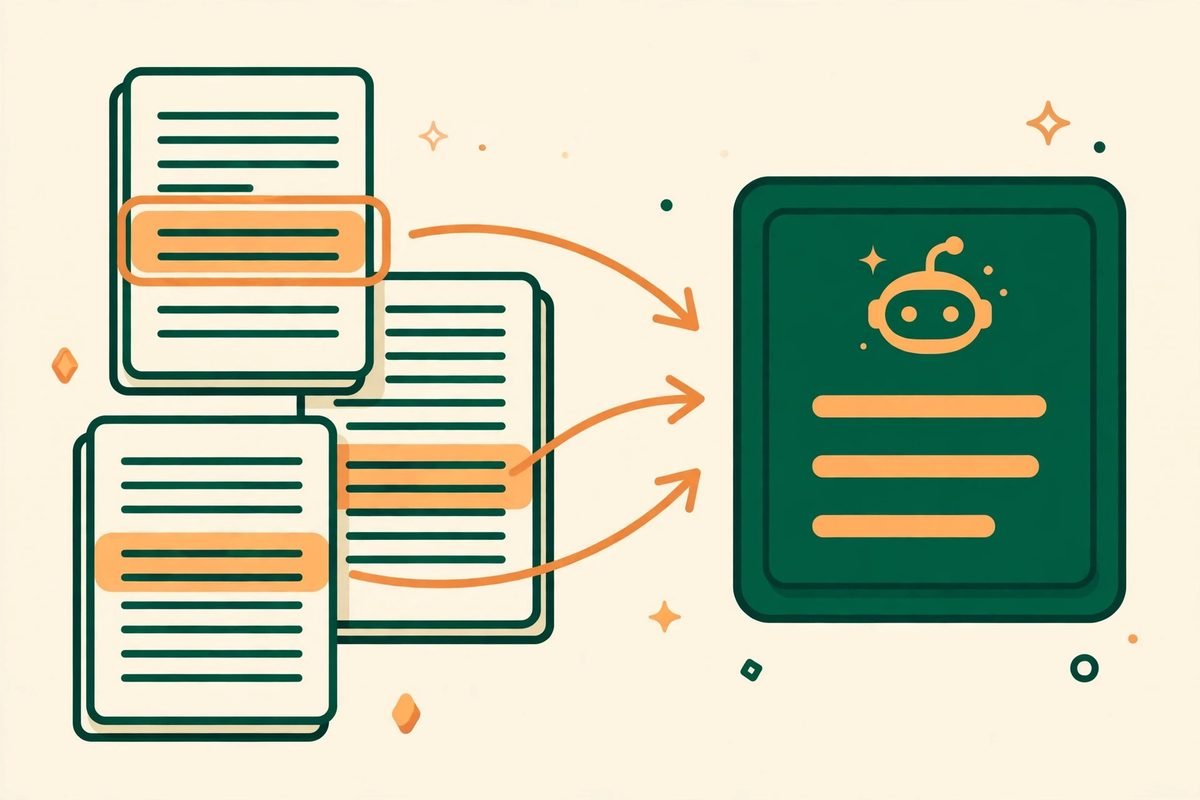
Dynamic Highlights is the more interesting engineering change. Instead of handing your agent the full text of every returned page, it selects the relevant tokens across all results, giving more space to the best pages and cutting repeated information. Exa says this uses 95% fewer tokens than full page text while improving answer quality. If that holds on your queries, the saving is larger than the $3 per 1,000 requests between Lite and Auto: token costs on the model side often dwarf the search bill itself, because a long context window is charged on every reasoning step that follows.
The third change is breadth. Billions of new structured documents across products, local businesses, flights, events, sports and weather mean that queries which previously returned thin or stale results — a flight time, a shop’s opening hours, a product variant — have a better chance of being answered from the index rather than from a second, specialised API call.
Exa 3.0 pricing: the verified tiers
Pricing is where this review can be precise, because Exa publishes per-request prices. The tiers that matter most are:
- Exa Lite search: $4 per 1,000 requests
- Exa Auto search: $7 per 1,000 requests
- Answer: $5 per 1,000 requests
- Deep search: $12 per 1,000 requests, and deep reasoning at $15 per 1,000 requests
- Contents, for fetching pages you already have URLs for: $1 per 1,000 pages
- Monitors, for scheduled recurring searches: $15 per 1,000 requests
New accounts also start with free credits, so a small evaluation costs nothing but engineering time. Check the pricing page on the day you deploy, because endpoint prices and credit amounts change, and a quote built on a launch-week price is a quote built on sand.
Do the arithmetic before you celebrate the Lite price. At 200,000 searches a month, Lite costs $800 and Auto costs $1,400 — a $600 monthly gap, or $7,200 a year, before any token savings. At 2 million searches, the gap is $6,000 a month. But the gap only matters if Lite answers as well as Auto on your queries. Third-party analysis of Exa’s own chart puts Lite at a score of about 79 against Auto at about 80.5 on the vendor’s task metric — roughly a 30% lower cost per task for a small quality gap. If your workload needs a second search to make up for a miss, that saving evaporates. The right metric is cost per correct answer, not cost per request, and only your own query log can tell you which tier wins on it.
Who Exa 3.0 is for
Exa 3.0 fits best where search is a recurring input to a product, not an occasional feature. That includes research and monitoring agents that run thousands of similar queries a day, where a cheaper search tier compounds into a meaningful margin improvement; lead-enrichment and company-intelligence pipelines, where the query shape is predictable and the answer is a structured fact; support and internal-knowledge bots that need fresh web facts before answering; and coding assistants that search for library usage, error explanations and changelog entries, where semantic matching beats keyword matching on the oddly phrased queries agents write.
It fits less well where the query is genuinely hard and open-ended — a multi-hop investigation across conflicting sources, a novel technical question with no canonical answer, or a compliance-sensitive lookup where a wrong answer costs more than a saved dollar. Those workloads belong on Auto or on a deep-search tier, with a human or a verification step in the loop, not on the cheapest pass available.
Watch-outs and honest limitations
First, the benchmark claims are self-reported. Exa says 3.0 ranks first on every benchmark it tested, including 91.8% on BrowseComp, 88.2% on DSQA, 56.1% on WideSearch, 42.0% on ATLAS, 75.5% on WebCode and 68.0% on FinSearchComp, against rivals including Perplexity, Brave Search and Parallel. Independent coverage notes that Exa has not published raw outputs or an independently reproducible test framework for those runs. That does not make the numbers false — they are specific, and therefore falsifiable — but you should not put them in a business case without running your own evaluation on a sample of your real queries, with ground-truth answers, before and after the switch.
Second, semantic search has a blind spot. It is excellent at finding pages that mean the same thing as your query, even when no keyword overlaps. It is weaker at exact-match lookups: an error string, a part number, a case-sensitive identifier, a quoted phrase. Exa does offer keyword modes for those cases, but if your workload is mostly exact lookups, a traditional SERP-style provider may mirror the ranking you expect more closely. Test both on your hardest exact-match queries, not only on your easiest semantic ones.
Third, effort escalation is the hidden cost. A pipeline that retries a failed Lite search on Auto, then escalates to deep search, then fetches full contents, can end up costing more than a single Auto call would have. Cap retries per effort level, log which tier actually produced each final answer, and set an alert on the share of queries that escalate. Without that discipline, a cost-saving tier becomes a cost-hiding tier.
How Exa 3.0 compares to alternatives
No single number settles a search-provider choice, because the providers price different things: some charge per request, some per token, some bundle search with a model. With that caveat, Exa Lite at $4 per 1,000 requests undercuts the commonly quoted $5 per 1,000 for Brave and Perplexity search APIs and $8 for Tavily’s basic tier, while Parallel’s fast tier is cheaper still at around $1 per 1,000 for simpler queries. Those are third-party comparisons drawn from pricing pages at a point in time; verify them before quoting, because every provider reprices.
The more useful comparison is architectural. SERP-style providers return pages ranked much as a human search engine would, which suits exact lookups and citation-heavy answers. Exa, Parallel and similar semantic providers return embedding-ranked results with compressed highlights, which suits agent loops that need signal in a small context window. If your agent’s bottleneck is context-window cost, the highlights design matters more than the headline price. Our earlier coverage of agent-search tools, in the AI Tools Directory, makes the same point from the other side: the cheapest search is the one you only have to run once, with an answer you can trust without a second call.
From our experience: how we would roll it out
If we were putting Exa 3.0 into a client product this week, we would not migrate everything at once. Start with a shadow run: send a sample of production queries — a few thousand, covering your most common shapes and your hardest 5% — to both Lite and Auto, and score them against known-good answers. Measure three things: correct-answer rate, tokens consumed downstream, and end-to-end latency. Only then decide the default tier per query shape, not per product. A common pattern that survives testing is Lite for structured lookups (company, product, price, opening hours) and Auto for open research, with deep search reserved for multi-hop investigations.
Then enforce the guardrails in code, not in documentation. Set a per-tier retry cap, a daily spend alert at a threshold you would actually act on, and a circuit breaker that falls back to your previous provider if the error rate crosses it. Cache aggressively where the answer is stable — company facts, documentation pages, product specifications — because the cheapest search of all is the one you never make. And keep the highlights, not the full pages, as the default context: feeding an agent ten full pages when it needed three paragraphs is the most expensive habit in agent engineering. Finally, revisit the choice quarterly; search pricing moves fast, and a launch-week decision should not be treated as permanent.
Frequently asked questions
What is Exa 3.0?
Exa 3.0 is the October 2026 release of Exa’s search engine for AI agents. It adds a larger embedding model, billions of new indexed documents, generally available Dynamic Highlights, and a new Lite search tier at $4 per 1,000 requests.
How much does Exa 3.0 cost?
Lite search costs $4 per 1,000 requests and Auto search costs $7 per 1,000 requests, with answer at $5, deep search at $12 to $15, contents at $1 per 1,000 pages and monitors at $15 per 1,000. New accounts start with free credits; always re-check the pricing page before budgeting.
Is Exa Lite good enough, or should I use Auto?
For predictable, structured lookups, Lite is usually good enough and materially cheaper. For open-ended research and hard multi-hop questions, Auto or a deep tier is the safer default. Decide from your own correct-answer rate per tier, not from the vendor’s benchmark chart.
What are Dynamic Highlights?
Dynamic Highlights select the relevant tokens across all search results, rather than returning full page text, which Exa says uses 95% fewer tokens while improving answer quality. In practice, that can cut downstream model costs more than the search saving itself.
Should a small business use Exa 3.0?
If your product or workflow already runs agent searches at volume, yes — start with the free credits and a shadow evaluation. If you only search occasionally, the saving is small and any reputable search API will do; pick on integration effort and citation quality instead.
Exa 3.0 is a welcome release for the right workload: cheaper, broader agent search with a genuinely useful token-saving feature. Its Lite tier is a real saving, not a gimmick, provided you measure cost per correct answer and keep escalation under control. Its benchmark leads are a reason to test it, not a reason to skip testing. Run the shadow evaluation, set the guardrails, and let your own query log decide whether Lite becomes your default — that is how a cost saving survives contact with production.
If you are building an agent product and want help choosing and integrating the search layer — or wiring the caching, guardrails and evaluation described here — talk to us about AI integration and automation, or contact us. We build these pipelines for clients every week, and we would rather help you measure the right thing than sell you the cheapest one.