
If you are building AI agents that need fresh web data, web scraping for AI agents is the unglamorous infrastructure problem nobody warns you about. LLMs are great at reasoning; they are terrible at fetching a JavaScript-heavy page behind Cloudflare. The verdict up front: HasData is a managed scraping service that turns any URL into JSON or Markdown with one API call, and it is one of the most practical ways to feed live web data into AI pipelines without running your own headless-browser fleet. It is not perfect — credit costs vary by endpoint, and the independent review base is thinner than the marketing suggests — but the fundamentals are strong. This review covers what it does, verified pricing, honest limitations, and how it stacks up against Apify, ScrapingBee, and rolling your own.
What Is HasData?
HasData is a US-based web scraping service (founded in 2022) built for product teams that need web data at scale. Its pitch is simple: send any URL, get clean JSON or Markdown back, with the company handling proxies, rendering, and retries in between. No more building scrapers that break every time a target site updates its markup.
The product comes in two flavours under one subscription: 63 API endpoints for developers, and 21 no-code scrapers for common targets like Google Search, Google Maps, and major e-commerce sites. You can start with a point-and-click scraper and graduate to the API on the same plan when a target gets demanding — a genuinely useful progression that most competitors force you to rebuild around.
The detail that matters most for AI work: output comes as structured JSON or Markdown. That Markdown option is clearly designed for feeding pages straight into LLM and RAG pipelines, and the company markets itself explicitly as a web scraping service for data pipelines and AI. Their AI extraction feature goes further — describe the fields you want, and it returns structured JSON without you writing CSS selectors.
How It Works: Rendering, Proxies, and AI Extraction
Under the hood, HasData runs three layers you would otherwise have to build yourself:
- Headless browser rendering. The company runs thousands of headless browser instances, so dynamic content, single-page apps, and client-side JavaScript render automatically. Their stated median response time is 1.9 seconds.
- Automatic proxy rotation. Requests route through a managed pool combining more than ten proxy providers plus a private residential network, with geo-targeting and IP rotation included in every call. This is the layer that kills most DIY scrapers — residential proxy management is a full-time job.
- Anti-bot adaptation and retries. HasData claims automatic adaptation to WAFs like Cloudflare and DataDome, with automatic retries on failed requests. Credits used on failed requests are refunded, and you only pay for successful requests — a pricing design that aligns the vendor’s incentives with yours.
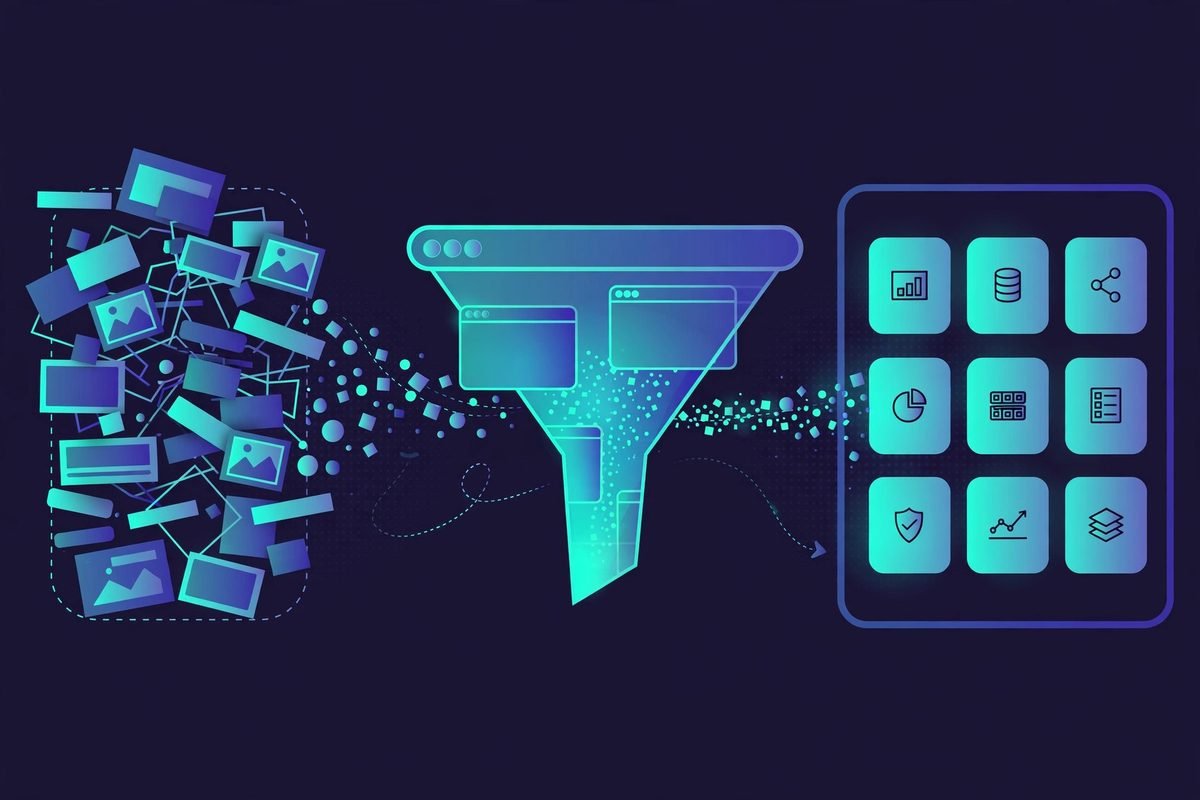
The AI extraction layer deserves a second look if you are feeding agents. Instead of selectors, you describe the schema you want and get structured data back. For RAG pipelines and agent tooling, that removes an entire maintenance surface: when a site’s markup changes, a selector-based scraper breaks silently and your agent starts hallucinating from garbage. AI-extracted output degrades more gracefully, though you should still validate schema on ingest.
HasData Pricing: What You Will Actually Pay
HasData uses fixed monthly plans with credits. Here are the self-serve tiers as listed on the official pricing page:
- Free — $0/month. 1,000 credits per month, 5 concurrent requests, every API and no-code scraper included, community support. No credit card required.
- Startup — $49/month. 200,000 credits per month ($0.25 per 1,000 requests), 5 concurrent requests, email support, 30-day free trial.
- Basic — $99/month. 1,000,000 credits per month ($0.10 per 1,000 requests), 15 concurrent requests, priority email support.
- Growth — $208/month. 3,000,000 credits per month ($0.07 per 1,000 requests), 50 concurrent requests, dedicated account manager.
- Enterprise — custom. Past 20 million credits a month, with SSO, security review, and shaped concurrency and support.
The critical nuance, flagged by an independent pricing analysis on prospeo.io: a “credit” is not one request. Depending on the endpoint and configuration, a request can burn 1 to 15 credits. The headline $0.07–$0.25 per thousand applies to base web-scraping endpoints; heavier endpoints cost more. For Google SERP APIs, the same analysis puts HasData at roughly $0.83–$2.45 per 1,000 requests depending on tier — lower-middle of the market, where Serper sits near $0.30 and SerpApi near $15.
Two genuinely user-friendly policies soften this: unused credits roll over into the next billing period, and one subscription works flexibly across both the APIs and the no-code scrapers. Before committing, run your real workload against the free 1,000 monthly credits and measure your actual credit burn — the headline per-1K numbers mean nothing until you know your per-request cost.
Who Should Use HasData (and Who Should Not)
HasData fits best when freshness and reliability matter more than squeezing the last cent per request:
- AI teams feeding RAG or agent pipelines. Markdown output plus AI extraction is purpose-built for this. Fresh web content into your retrieval layer, without maintaining a crawler.
- Price and competitor monitoring. Multiple reviewers cite exactly this use case — scheduled scrapes of product pages, clean data back, no proxy babysitting.
- SERP and local-directory data. Prebuilt Google Search, Maps, and directory scrapers cover the most common lead-gen and SEO-monitoring targets out of the box.
- Teams with no scraping infrastructure. If nobody on your team wants to own a headless-browser fleet, the managed route pays for itself quickly.
Skip it — or at least think twice — if you only need occasional one-off scrapes (open-source Crawlee or Crawl4AI will do), if your targets are simple static pages (a script with requests and BeautifulSoup costs nothing), or if you already run proxy infrastructure at serious scale and can amortise the engineering. And if your workload is purely Google SERP at volume, compare HasData’s SERP per-1K cost against dedicated SERP APIs like Serper before deciding.
Watch-Outs: The Honest Limitations
No tool review is useful without the downsides. Here is what we found:
- Credit burn is hard to predict from the pricing page. The 1–15 credits-per-request range means two identical-looking workloads can cost 15x apart. Budget from measured burn, not from headline rates.
- The independent review base is thin. The company advertises 4.8 stars across 100+ reviews on five platforms, but the individual samples are small — 17 reviews on Capterra, 40 on Trustpilot (where the score is a messier 4.3). Treat aggregate ratings with the usual scepticism.
- Docs and support have rough edges. A detailed G2 review praised the ease of the API but noted documentation that was not specific enough on parameters for some scrapers (the example given: a max-bed-count parameter on the Zillow scraper) plus slow support responses. Expect some trial and error on niche endpoints.
- No third-party benchmark inclusion. The prospeo analysis notes HasData was not included in Proxyway’s 2026 scraping API benchmark, so there is no independent head-to-head performance data — only the company’s own 1.9s median and 99.9% uptime claims.
- Scraping legality is your problem. HasData sells infrastructure, not legal cover. Scrape public data, respect terms of service and robots.txt, and get legal advice for anything that touches personal data or sits in a grey area. This applies to every scraping vendor, but it is worth saying plainly.
How It Compares to the Alternatives
The scraping-infrastructure market has four lanes, and HasData sits in the managed-API lane:
- Apify. The broadest actor marketplace — thousands of prebuilt scrapers plus the ability to write custom actors. More flexible for exotic targets, but pricing and quality vary by actor, and you are managing a platform rather than calling one API.
- ScrapingBee. A single developer API for rendering and proxy rotation. Simpler mental model, but less endpoint breadth and no no-code tier to start from.
- SerpApi / Serper. Pure SERP specialists. Serper’s ~$0.30 per 1K undercuts HasData’s Startup-tier SERP pricing meaningfully — if SERP data is all you need, a specialist is usually cheaper.
- Crawlee / Crawl4AI (open source). Free libraries, full control, zero vendor cost — but you own the browsers, the proxies, the retries, and the 3 a.m. outages. The right choice when engineering time is cheaper than a subscription, or when data must never leave your network.
HasData’s differentiator is the middle ground: broader than ScrapingBee, simpler than Apify, with a no-code on-ramp that the open-source tools cannot offer. The credit system is its weakest competitive point against flat per-request pricing — do the spreadsheet for your specific endpoints before assuming it is the cheapest option.
From Our Experience: What We Would Do on a Client Project
At MTD Technologies, we have built data pipelines that feed AI features for years, and the pattern is always the same: the scraper is easy, the scraping operation is what eats you. Proxy rotation, CAPTCHA handling, JavaScript rendering, and silent breakage when a site redesigns — that is a full-time job disguised as a side task. A managed service like HasData pays for itself the first time a target site rolls out a new WAF rule on a Friday.
For AI integration work specifically, the combination that matters is Markdown output plus AI-extracted JSON. It collapses two pipeline stages (fetch → parse) into one API call, and schema-described extraction degrades far more gracefully than CSS selectors when pages change. If we were wiring web data into a client RAG system or an AI agent this quarter, we would prototype against HasData’s free 1,000 credits, measure real credit burn across the actual target list, and only then decide between a managed plan and an open-source stack like Crawl4AI.
When would we not recommend it? Static sites with simple HTML — a ten-line script is free. One-off research scrapes — open source wins. And anything in a legal grey area, where the right move is a lawyer first and a scraper second. If your data pipeline needs to survive in production, though — workflow automation with scheduled, monitored scrapes feeding downstream systems — managed infrastructure is the pragmatic default. That is the kind of plumbing we build for clients every week.
Frequently Asked Questions
Is HasData good for AI agents and RAG pipelines?
Yes — this is arguably its strongest use case. It outputs Markdown (ideal for feeding pages into LLMs) alongside structured JSON, offers AI-powered extraction where you describe fields instead of writing selectors, and handles the proxy and rendering infrastructure that would otherwise break your agent’s data supply. Measure credit burn on the free tier before committing.
How much does HasData cost?
Plans run from a free tier (1,000 credits/month) through $49, $99, and $208/month, up to custom Enterprise. The headline rate is $0.07–$0.25 per 1,000 requests for base scraping endpoints, but requests can consume 1–15 credits depending on endpoint and configuration, so real cost depends on your workload. Unused credits roll over, and failed requests are refunded.
Is web scraping legal?
Scraping publicly available data is generally permissible in many jurisdictions, but it depends on what you scrape, how you access it, and local law. Respect terms of service and robots.txt, avoid personal data, and get legal advice for anything borderline. HasData provides the infrastructure — legal responsibility stays with you.
Does HasData offer a free plan?
Yes. The free plan includes 1,000 credits every month with no credit card required, covering every API endpoint and no-code scraper. Paid plans also include a 30-day free trial. The free tier is genuinely useful for prototyping and measuring your real credit consumption.
How does HasData compare to Apify?
Apify offers a broader actor marketplace and custom-actor flexibility, which wins for exotic or complex targets. HasData is simpler — one API, fixed plans, a no-code on-ramp — and positions itself around AI data pipelines with Markdown output and AI extraction. Choose Apify for marketplace breadth, HasData for managed simplicity, and compare per-endpoint costs for your actual targets.
Web scraping for AI agents is one of those problems that looks trivial until it runs in production. If you are building an AI product that needs live web data — a RAG system, a monitoring agent, a research tool — the question is never whether you can scrape, it is whether you want to own the infrastructure. HasData makes a credible case that you should not. Explore more tools in our AI tools directory, or talk to us if you need a production data pipeline built around your AI product.