
If you have ever reopened a coding agent after a weekend away and watched it ask you questions you already answered on Friday, you have felt the problem Claude-Mem solves. Persistent context across agent sessions is the difference between an agent that starts from zero every time and one that remembers what your project is, what you decided, and what already went wrong. Claude-Mem, an open-source project from thedotmack with more than 103,000 GitHub stars at the time of writing, is currently the most popular attempt to give coding agents exactly that kind of memory. This deep-dive explains what it actually does, how it works under the hood, and whether your team should adopt it.
It is written for engineering leads and agency teams who already use AI coding tools and are tired of re-explaining their codebase.
What Claude-Mem is
Claude-Mem describes itself as a persistent memory compression system built for Claude Code, and that description is precise. It is not a chatbot, not a model, and not a new coding agent. It is a layer that sits around your existing agent: it watches what the agent does during a session, captures observations about tool usage, decisions, bug fixes and findings, compresses those observations with AI into semantic summaries, and injects the relevant ones back into future sessions.
The project started as a Claude Code plugin, but the current README lists a much wider set of supported tools: Claude Code, OpenClaw, Codex, Gemini, Hermes, Copilot and OpenCode. The core promise stays the same: context should survive across sessions, so knowledge about a project compounds instead of resetting every time a conversation window closes.
Two numbers tell you why this project matters right now. At the time of writing it carries more than 103,000 stars and over 9,100 forks on GitHub, and it was updated on the same day this article was researched, at version 15.2.1. That velocity matters for a tool that hooks deeply into your workflow: an abandoned memory layer would be a liability.
What Claude-Mem can do
The feature list in the README is long, but five capabilities do the real work:
- Automatic capture. Lifecycle hooks fire on session start, prompt submission, tool use, session stop and session end. You do not write memory entries by hand; the system observes what the agent does and records it.
- Semantic summaries. Raw session activity is compressed into searchable observations, so a week of debugging becomes a handful of retrievable findings rather than a transcript nobody will ever reread.
- Progressive disclosure search. A dedicated mem-search skill retrieves memory in layers, cheapest first, instead of dumping everything into the context window at once. This is the feature that makes the whole idea affordable in tokens.
- Privacy controls. Content wrapped in
<private>tags is excluded from storage, and context injection can be configured in detail rather than left as all-or-nothing. - Team sharing, optionally. A feature called TeamBrain provides a shared workspace beside each person’s own memory, with member attribution and linked findings. Each person chooses what to share; personal requests and review notes stay separate.
There is also a local web viewer, called My Work, that shows live requests, progress, human handoffs and a saved review queue. This is where a lead developer can see what the memory layer actually recorded, which matters far more than any marketing claim: if you cannot inspect what your agent remembers, you cannot trust it.
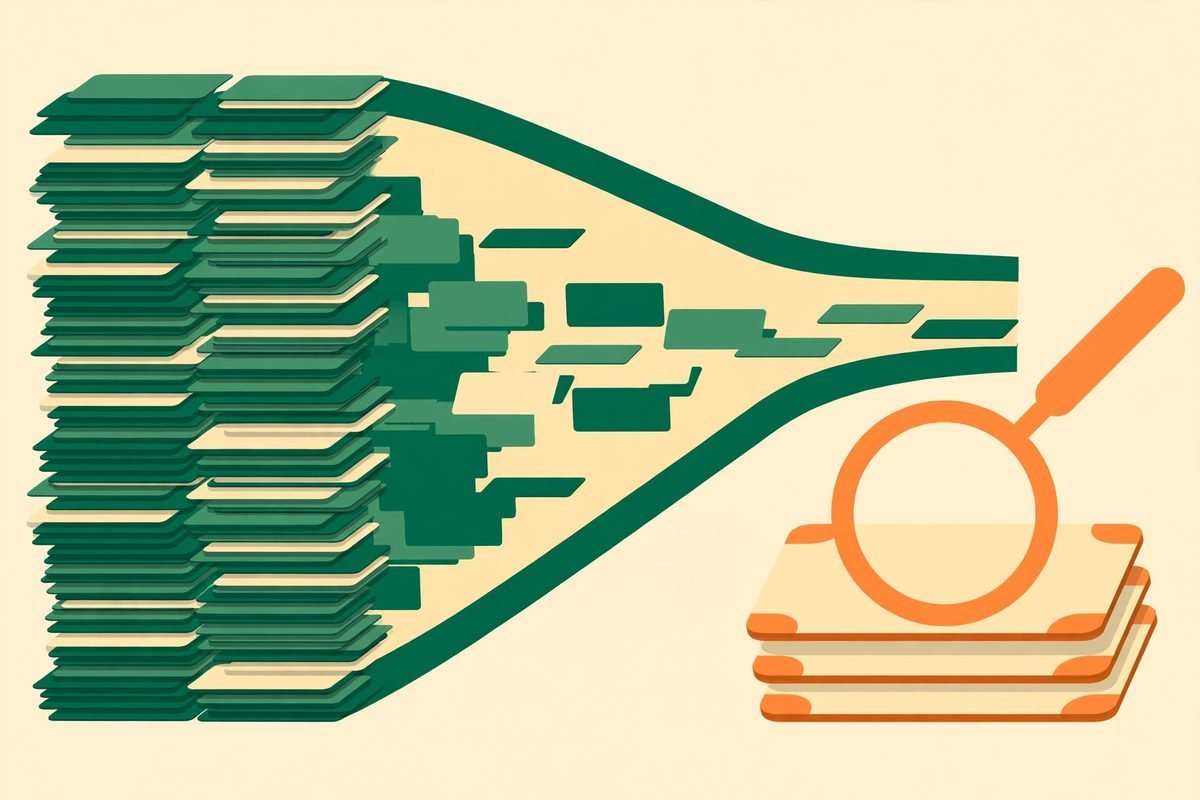
How Claude-Mem delivers persistent context across agent sessions
The architecture has six components, and understanding them explains both the strengths and the costs. First, lifecycle hooks run a small launcher on PATH for each agent event. Second, a smart installer checks cached dependencies on setup and repair. Third, a worker service exposes a local HTTP API with a web viewer UI, managed by Bun. Fourth, a SQLite database stores sessions, observations and summaries. Fifth, the mem-search skill handles natural-language queries with progressive disclosure. Sixth, a Chroma vector database provides hybrid semantic and keyword search.
System requirements are modest but specific: Node.js 20 or higher, a current version of Claude Code with plugin support, Bun and uv (both auto-installed if missing), and SQLite, which is bundled. Settings live in ~/.claude-mem/settings.json, created with defaults on first run.
The retrieval model is the part worth studying, because it answers the obvious objection: will memory not just bloat the context window? Claude-Mem uses a three-layer workflow. First, search returns a compact index, roughly 50 to 100 tokens per result according to the README. Second, timeline shows chronological context around results that look interesting. Third, get_observations fetches full details only for the filtered IDs, at roughly 500 to 1,000 tokens each. The README claims roughly ten times token savings from filtering before fetching, and while that figure is the project’s own claim rather than an independent benchmark, the direction is right: filtering before fetching is the only retrieval design that scales.
Why Claude-Mem is trending
Three forces are pushing agent memory to the top of GitHub trending at the same time. First, coding agents have become genuinely useful, which means teams now run dozens or hundreds of sessions against the same codebase, and the cost of re-explaining context is paid over and over. Second, context windows have grown, but they still reset: a bigger window does not remember last Tuesday. Third, agent skills and multi-agent setups have made sessions harder to reconstruct from chat history alone.
Claude-Mem sits at the intersection of all three. It does not ask you to change agents, and it does not ask you to write documentation you were never going to write. It harvests the documentation your sessions already contain.
From our experience: where agent memory helps, and where it bites
We build and maintain client software with AI-assisted workflows every week, and our view on agent memory is enthusiastic but qualified. Memory is most valuable exactly where human memory is weakest: the decision you made three sprints ago and never wrote down, the bug that took a day to diagnose and will recur in a slightly different form, the integration quirk that only one developer understands. A memory layer that resurfaces those findings when a new session starts is worth real money in saved rework.
But memory is not documentation, and treating it as documentation is the first mistake. Observations inherit session quality: a confident wrong conclusion, recorded once, can be injected into every future session until someone notices. That is why the review queue in the web viewer matters. If your team adopts Claude-Mem, have someone glance at what gets recorded during the first few weeks, the same way you would review a junior developer’s notes before trusting them.
The second honest limitation is staleness. Projects change and decisions get reversed, and a memory layer that cannot tell you when an observation was recorded, or whether it has been superseded, will eventually mislead. The timeline tool exists precisely for this, so check chronology on anything load-bearing rather than accepting a retrieved summary at face value.
The third limitation is operational overhead. A local worker, a vector database and a set of hooks are another moving part in every developer’s environment. For a solo developer that is fine. For a twenty-person team, it is a rollout that needs an owner, or half the team will quietly run without memory and wonder why results differ.
A responsible-use note: memory is sensitive data
Anything that records what your agents do will, sooner or later, record something sensitive: a credential pasted into a prompt, a client’s internal URL, an unreleased feature name. Claude-Mem’s <private> tags and configuration controls exist for this reason, but they only work if the team knows about them and uses them consistently. Treat the memory store like a production database: know where it lives, who can read it, and what happens to it when a developer leaves.
The hosted option deserves the same scrutiny. The installer offers a sign-in that provisions a memory key and unlocks the hosted observer with a 30-day free trial, falling back to your Anthropic plan when the trial ends, with no card required for sign-in. That is convenient, but convenience is not a data policy. If your client contracts restrict where project data may be stored, run the local provider path instead, and make that decision before the first session, not after the first sensitive observation is already synced. If you are unsure how a memory layer fits your delivery stack, our AI integration and automation team can review the setup with you before rollout.
Getting started with Claude-Mem
Installation is deliberately short. The steps below follow the project’s own quick-start:
- Check the requirements: Node.js 20 or higher and a current Claude Code install with plugin support. Bun and uv are installed automatically if missing.
- Run the installer with
npx claude-mem install. For OpenCode, usenpx claude-mem install --ide opencodeand restart OpenCode afterwards. - When prompted, sign in to provision your memory key, or skip the account step with an explicit provider flag or by setting the offline opt-in if you prefer a fully local setup.
- Restart Claude Code. Context from previous sessions should now appear automatically in new sessions.
- Do not install via a global npm install for this purpose: the README warns that
npm install -g claude-meminstalls only the SDK and does not register plugin hooks or set up the worker service. - Open the web viewer, check what the first sessions recorded, and mark anything sensitive with
<private>tags going forward. - Try the mem-search skill with a real question from your own project history, such as a bug you fixed last month, and judge it on whether it saves a re-explanation.
One practical tip: pilot it on a single project for two weeks before rolling it out team-wide. Memory quality is only visible over time.
Frequently asked questions
Is Claude-Mem free?
Claude-Mem is open source under the Apache License 2.0, so the code itself is free to use and embed. The hosted observer offered during installation includes a 30-day free trial and then falls back to your Anthropic plan unless you subscribe.
Does Claude-Mem work with tools other than Claude Code?
Yes. The project started with Claude Code, but the README lists OpenClaw, Codex, Gemini, Hermes, Copilot and OpenCode among the supported tools, with dedicated install commands for several of them. Support depth varies by tool, so verify your specific harness before committing a team to it.
Where is my agent memory stored?
Locally, in a SQLite database managed by the worker service, with a Chroma vector database for hybrid search. Settings live in ~/.claude-mem/settings.json. If you choose the hosted observer, memories sync to the provider’s cloud service, so the local-versus-hosted choice is a data-governance decision, not just a setup preference.
Can my team share one memory?
Yes, through the optional TeamBrain shared workspace, which sits beside each person’s own memory with member attribution and linked findings. Each person chooses what to share. For client work, agree the sharing rules before enabling it: what is shared, what stays personal, and who reviews shared findings.
Should a small business adopt Claude-Mem?
If your team already uses a supported coding agent daily and works on long-lived projects, yes, as a pilot: the rework it saves on repeated context is real. If your agent use is occasional or your projects are short and disposable, the setup and curation overhead will outweigh the benefit, and a good project README will serve you better. If you want help scoping that pilot, browse our AI Tools Directory, or talk to our team about your stack.
Claude-Mem earns its 103,000 stars by solving a problem every agent user recognises: agents that forget. Its weaknesses, stale observations, sensitive captures and rollout overhead, are manageable, but only if someone owns them. Adopt it as infrastructure, with a pilot, a reviewer and a data policy, and it will quietly compound your team’s knowledge.