
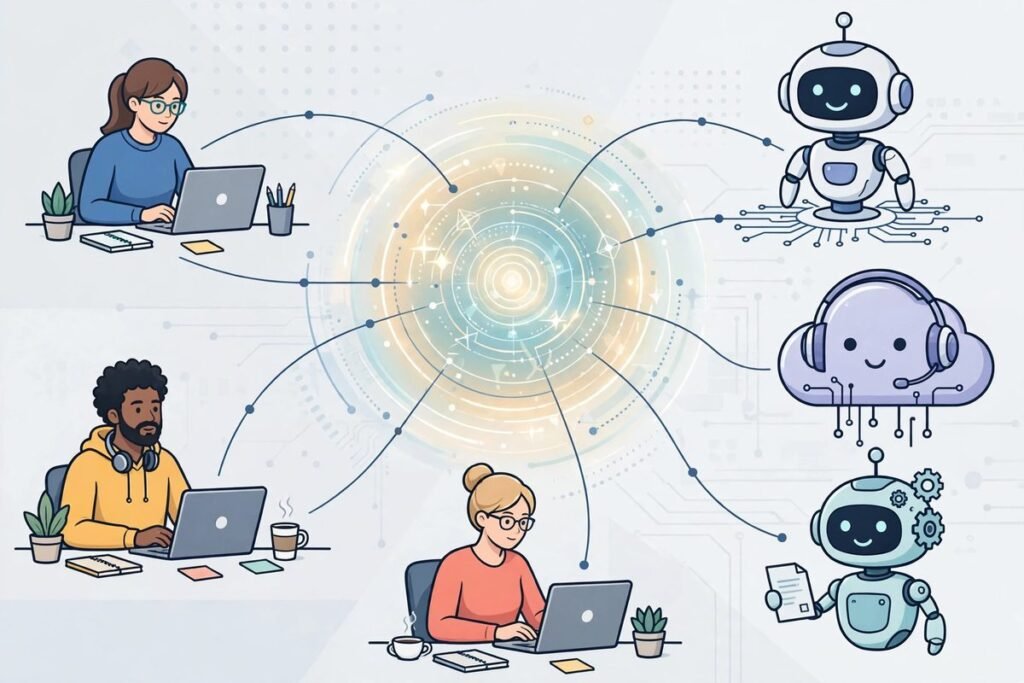
Context Engine is a shared memory for AI agents and teams: one place where Claude, ChatGPT, Cursor and Claude Code save what they learn as they work, and where the humans on the team can read it, question it and add to it. If your team already runs more than one AI assistant, that single sentence probably explains why the tool caught attention on Product Hunt within days of its October 2026 launch. Our verdict up front: it solves a real and growing problem, but it is an early product, and its value depends entirely on whether your team is willing to curate what the memory holds. Free to start, it is worth a controlled trial on one project before you let it anywhere near your whole workflow.
The problem it addresses is one we see in almost every agency engagement that involves AI coding assistants. A developer asks Claude Code to build a feature, the assistant learns the project’s conventions, naming rules and quirks, and then the session ends and all of that learning evaporates. The next developer, or the next tool, starts from zero and re-learns the same lessons, sometimes reaching different conclusions. Multiply that across a team of five people using three different assistants and you get a quiet productivity leak: repeated explanations, contradictory decisions and nobody quite sure which version of the truth the agents are working from.
Shared memory for AI agents and teams: what it actually does
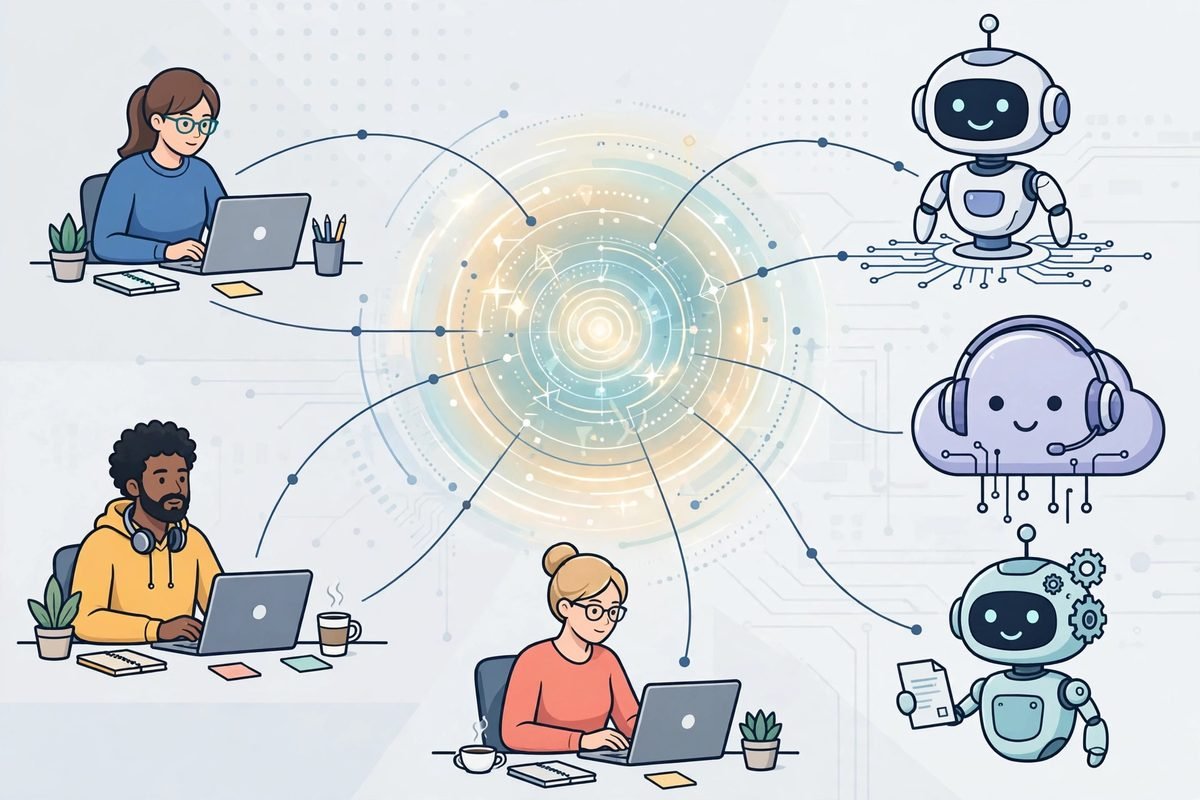
According to its Product Hunt listing, Context Engine is one memory for your AI agents and your team. The connected assistants save to it as they work, and the people on the team read it, ask it questions and add files. That two-way design is the important part. Most memory tools for coding agents are agent-to-agent only: a private archive that helps the next session pick up where the last one stopped. Context Engine adds the human side, so a project manager, a reviewer or a new joiner can open the same memory the agents are using and see what has been decided, what is in progress and what the agents believe to be true about the project.
In practical terms, the workflow it promises looks like this. An agent working in Cursor finishes a task and its notes, decisions and context land in the shared memory rather than dying with the session. A teammate opens ChatGPT later, asks what was decided about the authentication flow, and gets an answer drawn from that same memory instead of having to chase the original developer. A new team member adds a project brief as a file, and the agents working next week can draw on it without anyone re-pasting it into every conversation. The pitch is not that the memory is clever; it is that the memory is shared.
Three consequences follow from that design, and they are worth weighing before anything else. First, onboarding gets cheaper: a new agent or a new hire inherits context instead of reconstructing it. Second, consistency improves: when every assistant reads the same notes, they are less likely to invent conflicting conventions. Third, and less comfortably, errors get shared too. A wrong decision saved once can now mislead every agent and every teammate who reads it afterwards. That third point is not a reason to avoid the tool, but it is the reason the tool needs governance, which we come back to below.
Pricing: free to start, and what that does not tell you
Context Engine is listed on Product Hunt as free to start, with a listed price of zero. That is the full extent of what we could verify about its pricing at the time of writing: the listing does not publish paid tiers, per-seat rates or usage limits, and we could not find a public pricing page that confirmed them. We are stating that plainly rather than filling the gap with a guess, because invented pricing is exactly how a review misleads a buyer.
What this means for a buyer is straightforward. The free starting point makes a trial cheap, but it does not tell you what the tool will cost once your team actually depends on it. Before you roll it out beyond a pilot, confirm three things directly with the vendor: what the paid tiers cost and what limits they carry, whether there are per-seat or per-project charges, and what happens to your stored memory if you stop paying or cancel. A memory layer is stickier than most tools: once your agents and your team both rely on it, migrating away is a project in itself, so the exit terms matter as much as the entry price. Treat any tool in this category the same way you would treat a database, not a browser extension.
Who it is for, and who should skip it
Context Engine fits teams that already use two or more AI assistants across the same projects. If your developers switch between Claude Code and Cursor, or your content and engineering work passes between ChatGPT and an IDE assistant, the shared memory removes real friction. It also fits small agencies and product teams where knowledge currently lives in chat history and in one person’s head, and where a handover or a holiday currently means re-explaining the project.
It is less useful, for now, for a solo developer using a single assistant on a single codebase. In that setup the assistant’s own session history and a well-kept project notes file already cover most of the benefit, and adding a shared layer adds a dependency without adding much leverage. It is also a poor fit for teams that cannot commit to curating the memory. If nobody owns it, the archive will accumulate stale decisions, and a stale shared memory is worse than no memory at all, because it speaks with the confidence of a record while being out of date.
Watch-outs: the honest limitations
The most useful criticism of this tool so far has come from its own Product Hunt commenters, and it clusters around four questions that any buyer should ask. First, provenance and decay: when an agent saves something, can the team see where it came from, and does anything ever expire or get flagged as stale? A memory with no decay mechanism slowly fills with rules that were true in March and wrong by October. Second, corrections: when a teammate corrects something an agent saved, does the agent stop saving the wrong version again, or does the old habit reassert itself next session? Third, guardrails: with several people adding to one memory, what stops an accidental or careless edit from misleading everyone else, and can some contributors be treated as authoritative over others? Fourth, review separation: if the same memory feeds both the agent that writes code and the agent that reviews it, the reviewer may simply agree with decisions it has already absorbed, which defeats the purpose of an independent check.
None of these are exotic concerns; they are the ordinary failure modes of any shared knowledge base, and they are amplified when the readers are machines that do not pause to doubt what they are told. Until the vendor documents how it handles provenance, correction, permissions and decay, treat those four questions as your trial checklist. Run the pilot with them in mind, deliberately plant a wrong note, correct it, and watch what the agents do next. That one experiment will tell you more than any feature list.
How it compares to the alternatives
The shared-memory category is crowded, and the names are confusingly similar, so it is worth separating the neighbours. ResumeContext is a closer cousin: it syncs what Claude Code, Codex, Cursor and similar tools already write to disk into one archive per project, handed back through MCP, with the emphasis on resuming work across agents rather than on human-readable team memory. Kumiho Memory takes a different philosophical route, storing beliefs that evolve, with decision history and the reasoning behind changes preserved, and an open-source library behind a managed cloud. Make0 Brain pitches a portable personal memory layer across ChatGPT, Claude and Cursor. Context Engine’s distinguishing claim is the human side: the team does not just benefit from the memory, it reads and edits the same memory the agents use.
Two other products share the name and are not this tool. Neo4j’s Context Engine, announced in October 2026, is an enterprise ontology and GraphRAG layer for agents working over business data, currently in private preview with no published price. Salesforce’s Agent Context Engine is a governed context layer built on its Data 360 platform for agents across Agentforce, Google ADK, AWS Bedrock and similar frameworks. If you search for this tool and land on either of those, you have found a different product at a different price point for a different buyer. The Product Hunt tool reviewed here is the small-team, free-to-start one.
The do-it-yourself alternative is also real: a disciplined project notes file in version control, plus each assistant’s own memory features, gets a solo developer or a tiny team most of the way there for free. What you give up is the automatic capture: with the DIY route, context only enters the record when a human writes it down, and humans under deadline do not write things down. The case for paying for a tool like Context Engine is the capture, not the storage.
From our experience: memory is a garden, not a vault
We build AI-assisted workflows for clients, and the pattern we see repeatedly is that teams buy a memory tool and then neglect it. The tool is not the system; the curation habit is. If you trial Context Engine, assign one owner for the pilot, and give that person a weekly half-hour to prune: delete decisions that were reversed, correct notes the agents keep re-saving wrongly, and split project memory from personal preference. Keep two kinds of context apart deliberately: durable project truth, such as architecture decisions and client constraints, and working notes, such as what was tried this week. When the two mix, agents quote working notes as if they were decisions.
Two practical rules have saved our clients real money. First, never let the reviewing agent read the same memory as the building agent on work that needs an independent check; give the reviewer a clean brief and let it find the problems. Second, pilot on one project with two or three users for at least a month, and measure something concrete: how often does a new session still ask a question the memory should have answered, and how often does an agent act on a note the team knows is stale? If the first number does not fall and the second does not stay near zero, the tool is adding ceremony rather than capability, and you should not expand it. A shared memory that nobody trusts will simply be routed around, and then you are paying for a shelf nobody reads.
Frequently asked questions
What is Context Engine?
Context Engine is a shared memory tool launched on Product Hunt in October 2026. AI assistants such as Claude, ChatGPT, Cursor and Claude Code save to it as they work, and the human team reads it, asks it questions and adds files, so agents and people work from the same record.
Which AI tools does Context Engine work with?
Its listing names Claude, ChatGPT, Cursor and Claude Code. If your stack centres on a different assistant, confirm support with the vendor before committing, because the value of a shared memory depends entirely on the tools your team actually uses being connected to it.
Is Context Engine free?
It is free to start, according to its Product Hunt listing. Paid tiers were not publicly documented at the time of writing, so confirm pricing, limits and exit terms with the vendor before rolling it out beyond a pilot.
What happens when an agent saves something wrong?
That is the central risk of any shared memory: a wrong note can mislead every agent and teammate that reads it afterwards. Before adopting the tool, test its correction behaviour in a pilot: plant a wrong note, correct it, and check whether agents stop re-saving the wrong version, and whether provenance and stale entries are visible to the team.
Is it the same as Neo4j Context Engine or Salesforce Agent Context Engine?
No. Those are separate enterprise products that happen to share the name: Neo4j’s is a business-ontology GraphRAG layer in private preview, and Salesforce’s is a governed context layer on its Data 360 platform. This review covers the free-to-start Product Hunt tool for small teams.
Context Engine is worth trying if your team already juggles several AI assistants and is willing to own the curation habit that makes a shared memory trustworthy. Start free, pilot on one project, test the correction behaviour, and only then decide whether it earns a place in your stack. If you would like help setting up AI-assisted workflows, shared memory layers or automation that your team can actually maintain, explore our AI integration and automation services or our n8n workflow automation, browse the AI Tools Directory for more reviewed tools, or contact us to talk through your setup.