
PageIndex is a vectorless, reasoning-based RAG document index that has earned more than 39,000 GitHub stars by attacking the weakest part of most retrieval systems: finding the right passage in a long, complex document. If your team has watched a chatbot answer confidently from the wrong paragraph of a 400-page report, this project targets exactly that failure, replacing the vector database and chunking pipeline with a hierarchical tree index that a language model reasons through like a human expert finding the right section.
This deep-dive is for business owners, product teams, and developers who run document-heavy workflows. By the end, you will know what PageIndex does, how it works, what it costs, and where it genuinely beats vector search — and where it does not. Numbers below come from the project’s own repository and documentation, flagged as vendor-reported where relevant.
What PageIndex actually is
PageIndex, published by VectifyAI as VectifyAI/PageIndex, is an open-source Python project under the MIT licence, with about 39,712 stars and 3,429 forks, last updated on 26 October 2026. Its one-line description — “Document Index for Vectorless, Reasoning-based RAG” — is unusually accurate.
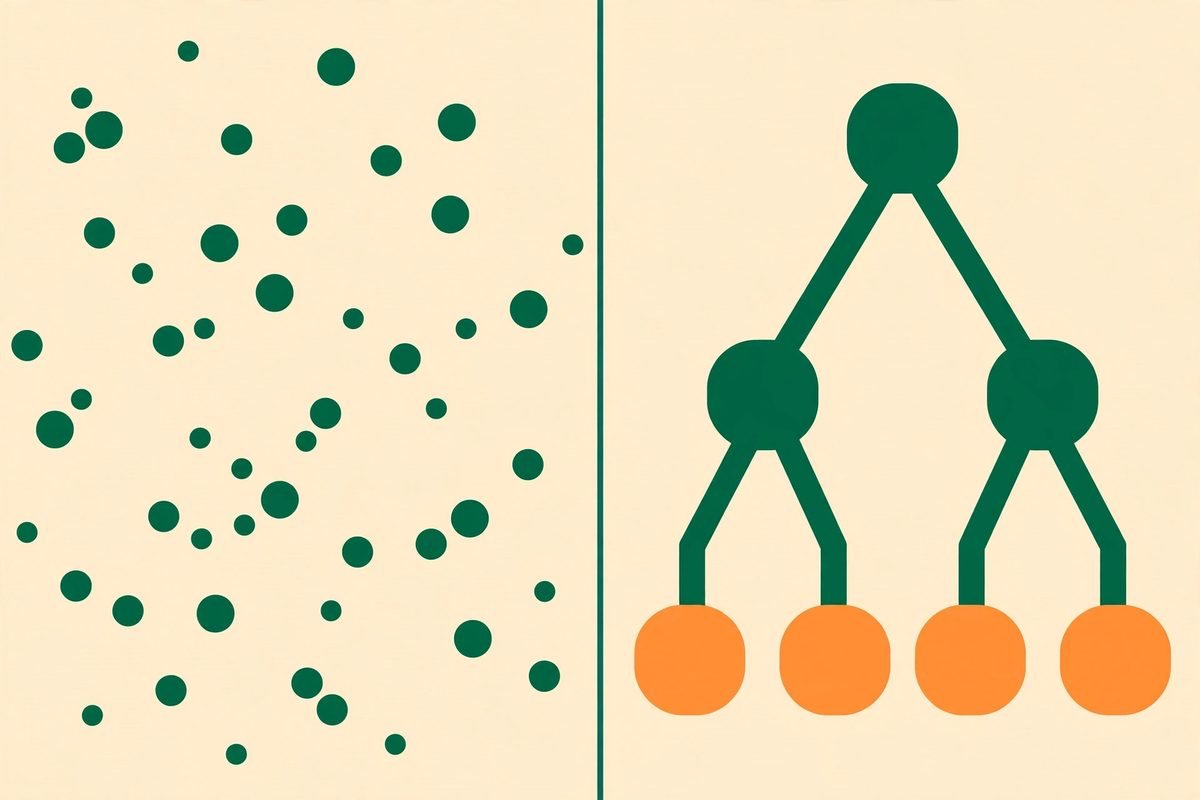
Most retrieval-augmented generation (RAG) systems work like this: split a document into chunks, turn each chunk into a vector embedding, store those vectors in a database, and at question time retrieve the chunks closest to the question’s vector. That is semantic similarity search. PageIndex’s core argument is simple and, in our experience, largely correct: similarity is not relevance. A passage can be semantically similar to a question without answering it, and the passage that answers it can use entirely different wording. On short help articles the gap rarely matters. On financial reports, contracts, and technical manuals — where meaning depends on structure, tables, footnotes, and cross-references — it matters a great deal.
PageIndex is designed for exactly those documents: financial reports, legal documents, regulatory filings, technical manuals, medical literature, and academic textbooks. If your documents are short web pages, this is probably not the tool you need. If they are the kind people currently search with Ctrl+F and a prayer, keep reading.
What it can do
- Tree indexing instead of chunking. Each document gets a hierarchical index mirroring its own sections and subsections, not a pile of fixed-size fragments.
- Reasoning-based retrieval. A language model navigates the tree, deciding which branches to explore and which to skip, instead of returning the nearest vectors.
- Traceable answers. Retrieval follows explicit tree nodes, so answers trace to specific references: page-level citations locally, block-level in the cloud.
- Chat with full context. Retrieval can use conversation history and domain knowledge, not just the latest question’s embedding.
- Local and cloud modes, one client. Index on your machine with your own model key, or hand indexing and storage to PageIndex Cloud while keeping your preferred chat model.
- Corpus-scale search. The PageIndex File System is a file-level tree layer that reasons over an entire corpus, not just one document.
- Agent integration. Tools drop into the OpenAI Agents SDK, Claude Agent SDK, or other frameworks, so an agent can search documents as a tool.
- Fast indexing. PageIndex Flash, added in August 2026, is a fast tree-index method for text-based PDFs and the local-mode default.
Two features change the evaluation. The index model need not be your strongest: the tree is extracted from document layout without a language model, and the index model only summarises it. The answering model matters far more, because it reasons over the tree. Budget accordingly: cheap indexing, serious answering.
How a vectorless, reasoning-based RAG document index works
Step 1: Index. PageIndex builds a tree-structure index for each document — a detailed table of contents a machine can navigate, with summaries at each node so a reader can tell what lives under each branch without reading the whole document. Indexing happens once; every later question reuses it, which is why per-question cost stays flat as documents get longer.
Step 2: Retrieve. When a question arrives, the chat model searches the tree agentically, reasoning about which branches hold the answer, reading those nodes, and following the trail deeper where needed. Vector search, by contrast, returns a ranked list of chunks in one shot and never reconsiders. The tree walk is slower and more expensive in tokens — the honest trade-off — but it can recover from a misleading first guess and leaves a trail showing where the answer came from.
The project’s comparison is blunt: vector RAG produces opaque results; PageIndex produces traceable ones. That is fair criticism of naive vector RAG, though modern systems with reranking and hybrid search are stronger than the caricature. The real question is whether tree reasoning is worth its extra query cost for your documents — the next sections give you the numbers to judge that.
Why it is trending now
Three forces explain why a document-indexing project has gathered nearly 40,000 stars. First, RAG is no longer a demo technology. Businesses have shipped chatbots over real documents and found the failure mode that matters: confident answers drawn from the wrong section. When a finance chatbot quotes last year’s margin as this year’s, or a compliance assistant cites a superseded clause, the problem is retrieval, not generation.
Second, the documents that matter most keep getting longer, routinely running to hundreds of pages. Handing the whole document to the model on every question gets more expensive with every page and eventually stops working: at 805 pages, the project’s measurements show, it no longer fits in the context window at all. A system whose query cost does not grow with length is therefore the only design that scales.
Third, traceability is now a buying criterion. In regulated work, “the AI said so” is not an audit trail; a path pointing to a specific section lets a human verify an answer in seconds. That is why this project resonates beyond developers: it speaks to the person who signs off on the answer.
The numbers: cost, speed, and accuracy
All figures here are project-reported from the repository README and its linked benchmark repository. Treat them as the vendor’s best case, not independent verification — but the methodology is published for anyone who wants to reproduce it.
- Indexing cost: about $0.001 per page. A 1,000-page textbook costs a little over a dollar to index, once, with a basic model. Every later question reuses that index.
- Indexing time: roughly 13 seconds to 4.5 minutes for documents from 9 to 1,098 pages in the project’s local setup, scaling predictably with length.
- Query cost vs. native PDF input: 2.1 times cheaper at 52 pages, rising to 16.6 times cheaper at 420 pages, because PageIndex reads only the tree nodes its reasoning reaches.
- FinanceBench accuracy: 98.7% claimed against 50% for vector RAG in the project’s chart. FinanceBench is a real, public benchmark, but this is the project’s own reported result — read it as evidence the approach can be dramatically better on financial documents, not a guaranteed score on yours.
- A dedicated financial QA benchmark compares 34 configurations of 19 models answering 100 questions over 40 Form 10-K filings from 8 companies. Full results and reproduction instructions are published in the benchmark repository.
The takeaway: indexing is cheap and one-off, so judge query cost and answer quality on your worst documents — the long, dense ones where vector search embarrasses you. Pilot PageIndex there first, with questions whose answers you already know.
From our experience: where this helps, and where it does not
At MTD Technologies, we have built RAG chatbots for businesses for years — including the grounded chatbots in our RAG chatbot guide — and the pattern behind PageIndex matches real client work. Vector search is excellent for short, self-contained documents in consistent language. It degrades exactly where PageIndex says it does: long documents, answers combining two distant sections, questions phrased differently from the document’s vocabulary, and tables or footnotes carrying the decisive detail.
Three gotchas. First, tree quality depends on structure: a clean PDF indexes beautifully, a scanned or chaotic one will not — where cloud OCR earns its keep. Second, reasoning-based retrieval costs more per question than a vector lookup. For thousands of casual daily questions over short documents, vector search may still win on economics. Third, traceability only helps if someone checks: a citation nobody clicks is theatre, not governance. Build verification into finance, legal, and compliance workflows.
Skip PageIndex when documents are short, volume is huge and the accuracy bar is low, or you cannot afford a strong chat model per query. Evaluate it when wrong-section answers already cost you credibility, documents run to hundreds of pages, or an auditor will ask “where exactly did that answer come from?”
Getting started in five steps
- Install the package. Run
pip install -U pageindexin a Python environment. No vector database to provision. - Set your model key. Local mode uses your own API key, set as an environment variable such as
OPENAI_API_KEY. With a Claude subscription, thepageindex[claude]option lets usage run through your plan instead. - Create a client and submit a document. Build a
PageIndexClientwith an index model and a chat model, callsubmit_document("report.pdf")to get a document ID, then callchat()with your question and that ID. - Test with questions you can already answer. Before showing the system to users, run 20 to 30 questions from real support tickets or analyst queries, and check each answer against its cited section. That tells you more than any benchmark.
- Decide local vs. cloud before you scale. Local mode keeps documents on your machine and suits text-based PDFs. Scanned documents, OCR, block-level citations, and an MCP server are cloud territory — involve compliance before migrating. The README publishes no cloud pricing tiers, so confirm them on the developer portal.
A responsible-use note
PageIndex makes answers traceable; it does not make them correct. A well-cited answer can still be wrong if the model misread the section, and vendor benchmarks are measured on the vendor’s documents, not yours. Do not deploy it for financial advice, legal interpretation, or medical decisions without human verification and a clear statement of its limits. Use human-in-the-loop for high-stakes answers and full automation only for low-stakes ones.
Frequently asked questions
Is PageIndex really free?
The open-source engine is MIT-licensed and free to use. You still pay for the models it calls: a basic model for indexing, a stronger one for answering. The hosted cloud version is a separate service — confirm its terms and pricing on the developer portal.
Does PageIndex work without a vector database?
Yes, and that is the point. It builds a hierarchical tree index from the document’s own structure and retrieves by letting a language model reason over that tree. There is no vector database to provision, tune, or pay for, and no chunking step to configure.
What kinds of documents is it best for?
Long, complex professional documents: financial reports, legal documents, regulatory filings, technical manuals, medical literature, and textbooks. Short, simple documents rarely need it.
How does it handle scanned or image-heavy PDFs?
Local mode is designed for text-based PDFs. Scanned and image-rich documents, OCR, and image understanding are cloud features. If your corpus is mostly scanned paper, evaluate the cloud version, or digitise cleanly first.
Can I use PageIndex inside my own AI agent?
Yes. It documents integration with the OpenAI Agents SDK, the Claude Agent SDK, and other frameworks, and the cloud version exposes an MCP server — so an agent can treat document search as a tool call.
PageIndex will not replace vector search everywhere, and it does not claim to. It offers a credible answer to the problem limiting most business RAG systems: finding the right passage in a long document and proving where it came from. If that is your problem, evaluate this repository first — one hard document, twenty known questions, an honest scorecard. For help building that evaluation, talk to MTD Technologies, explore our AI Tools Directory, or see our AI integration and automation services.